1Technical University of Darmstadt
2Robotics Institute Germany (RIG); DFKI; hessian.AI
TLDR: Train one multi-embodiment policy and value function, then design hundreds of new robots with value gradients in just minutes.
Explore the Designs
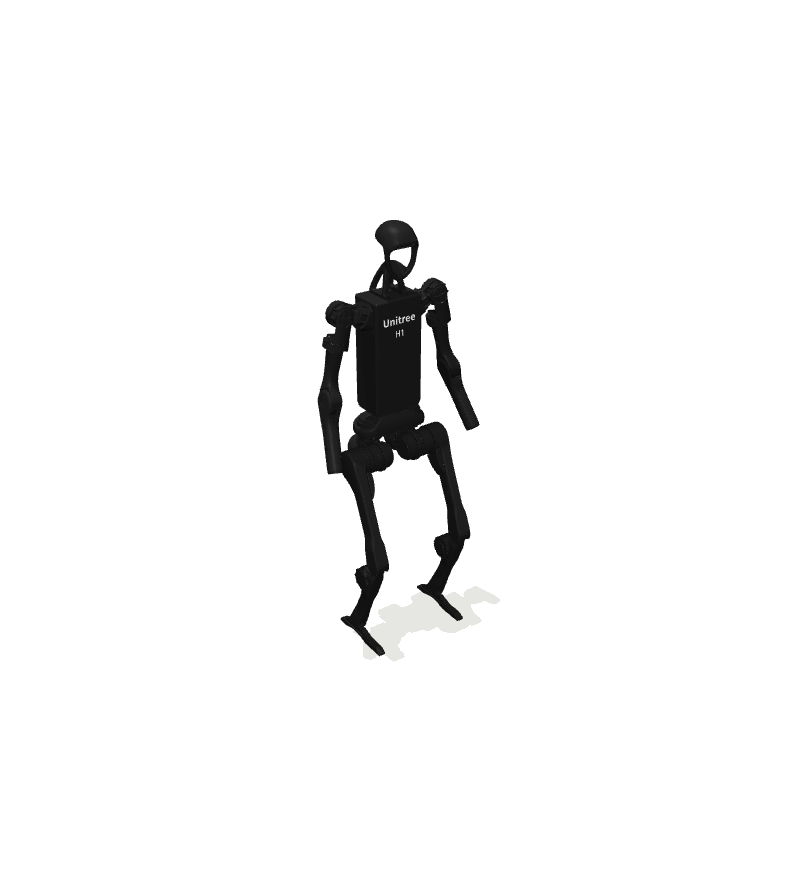
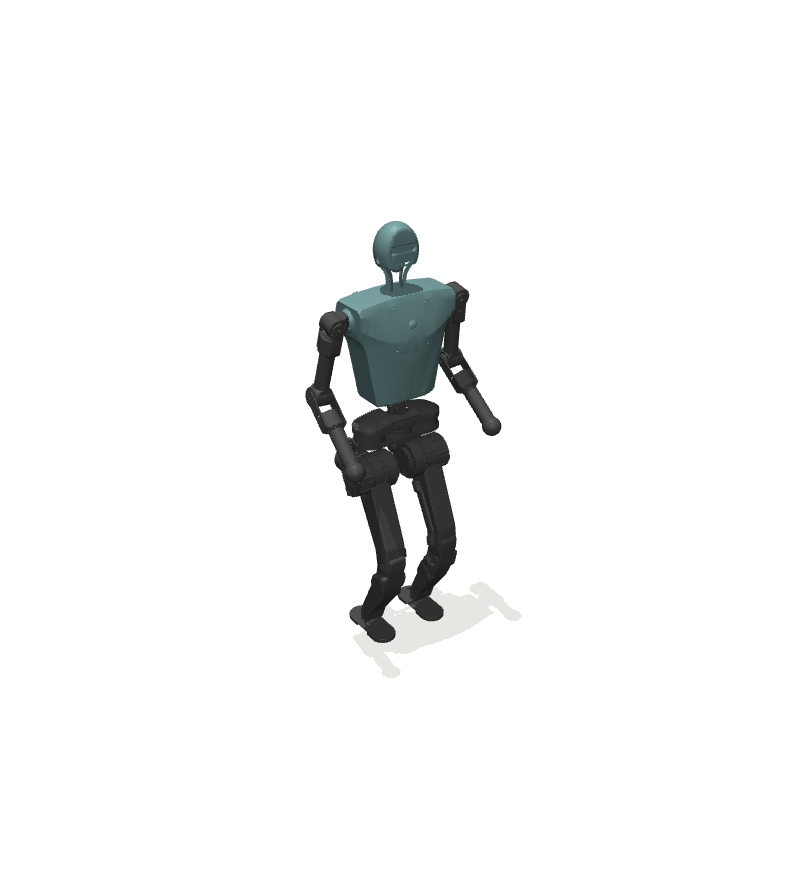
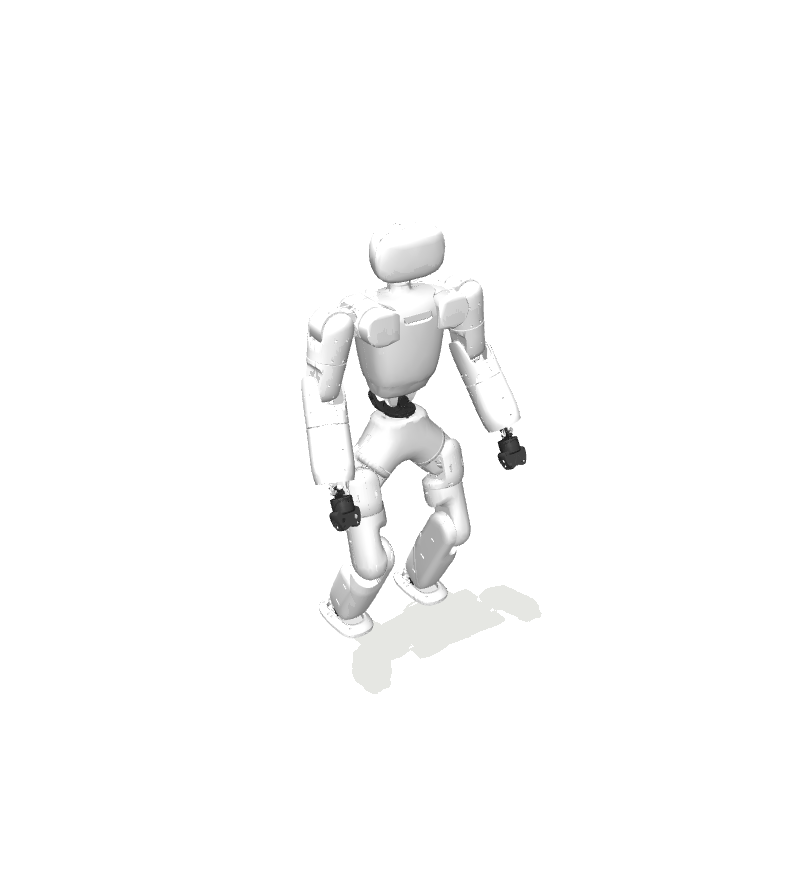
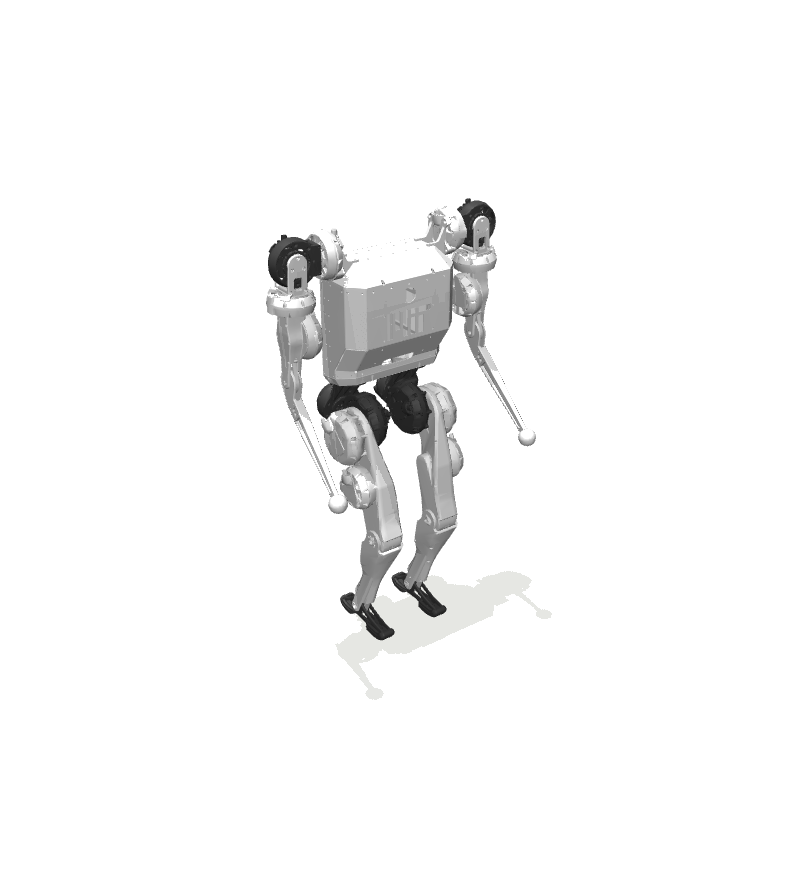
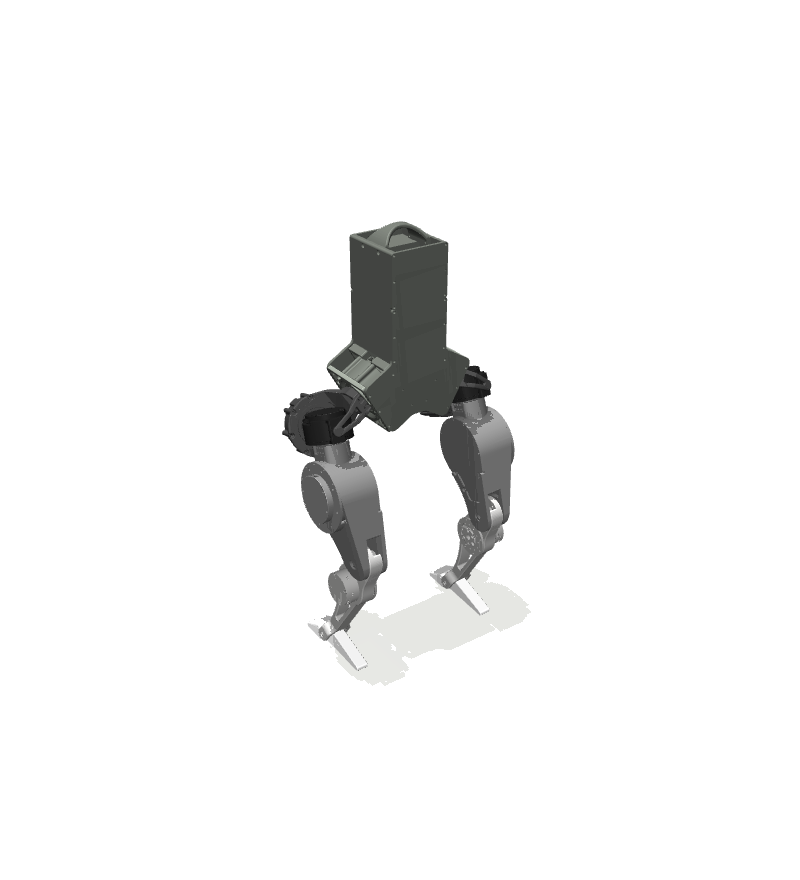
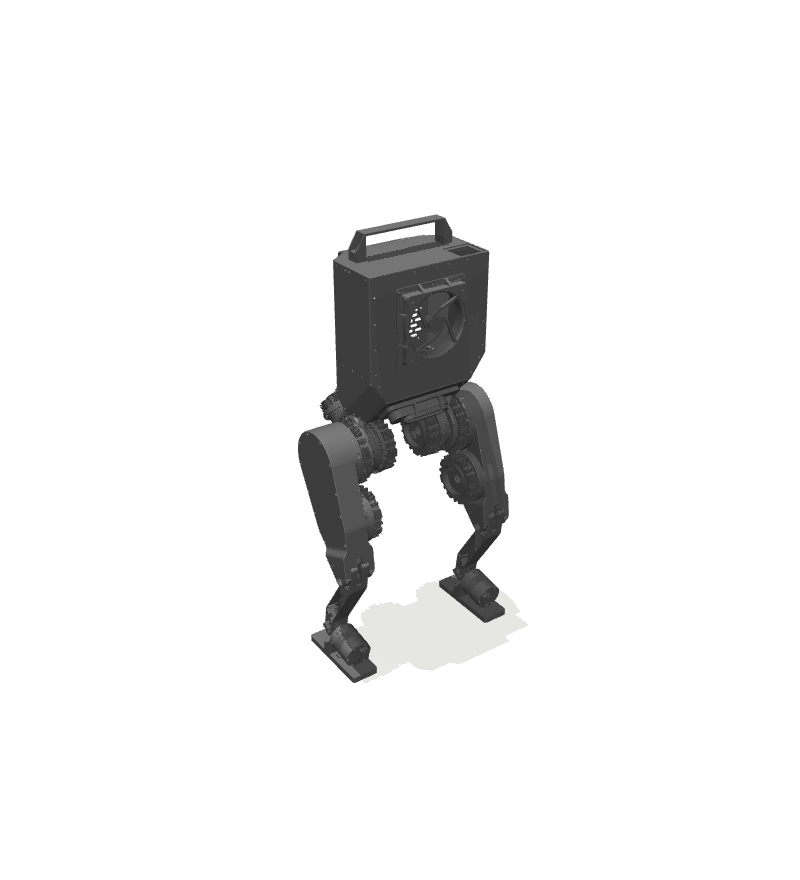
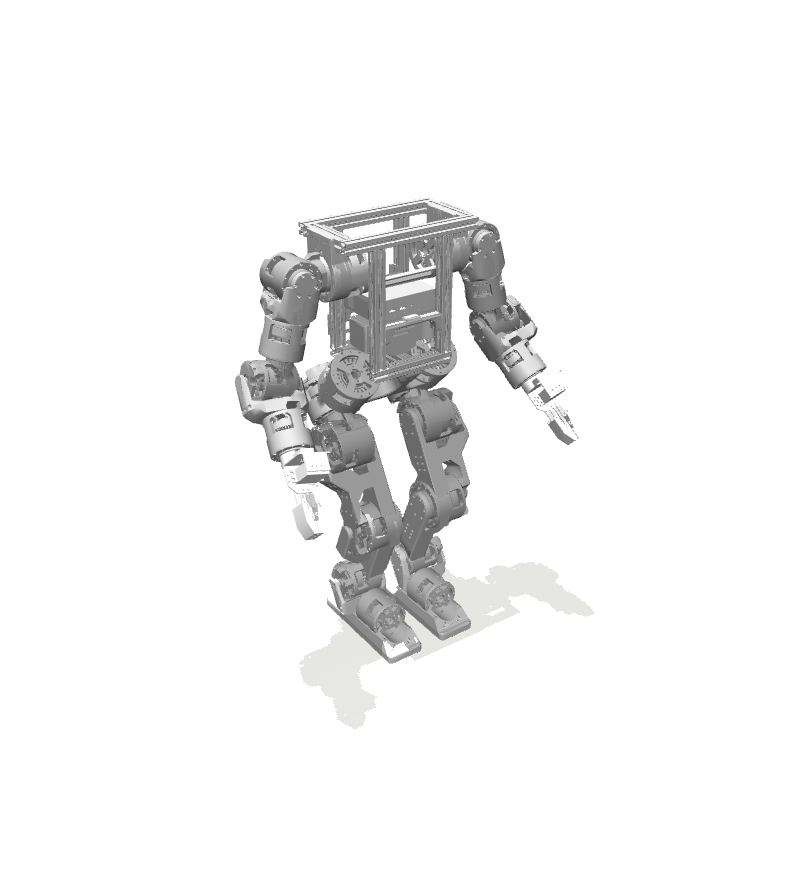
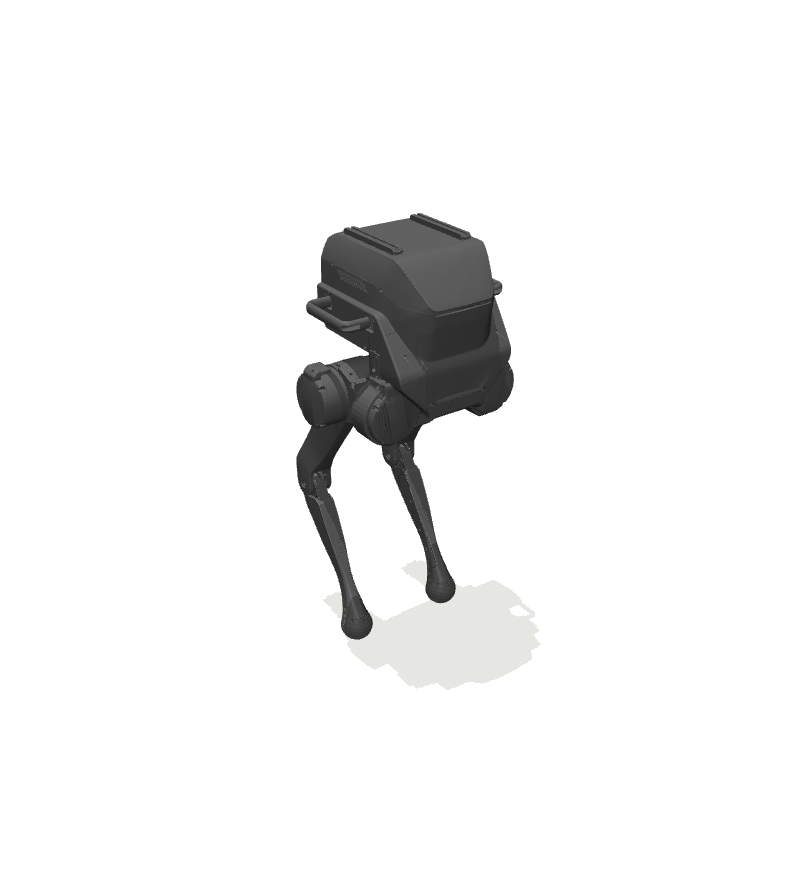
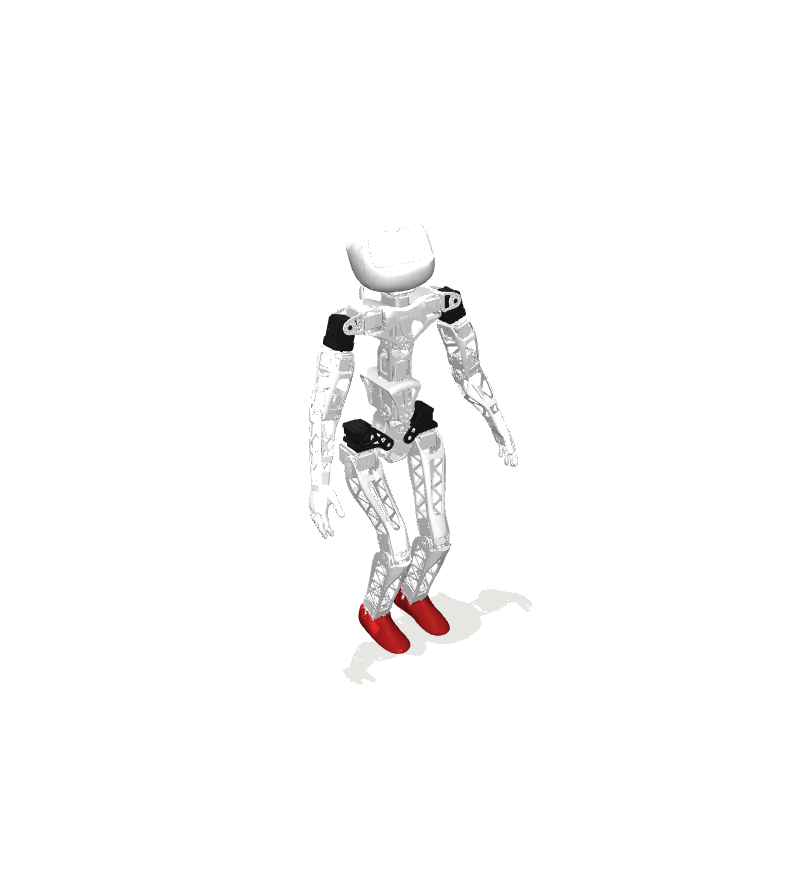
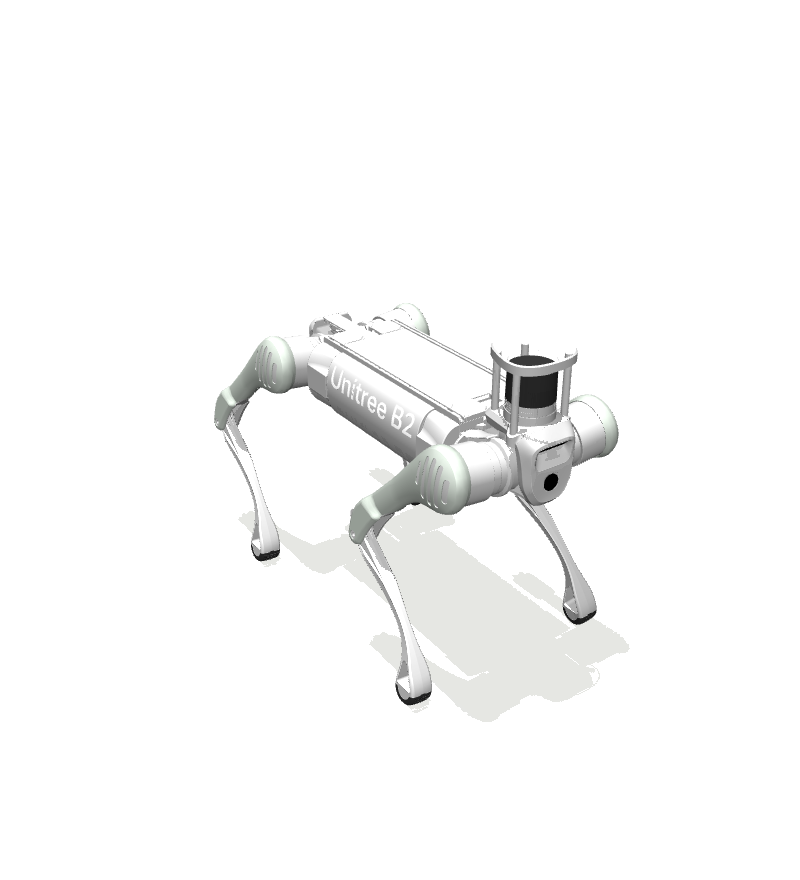
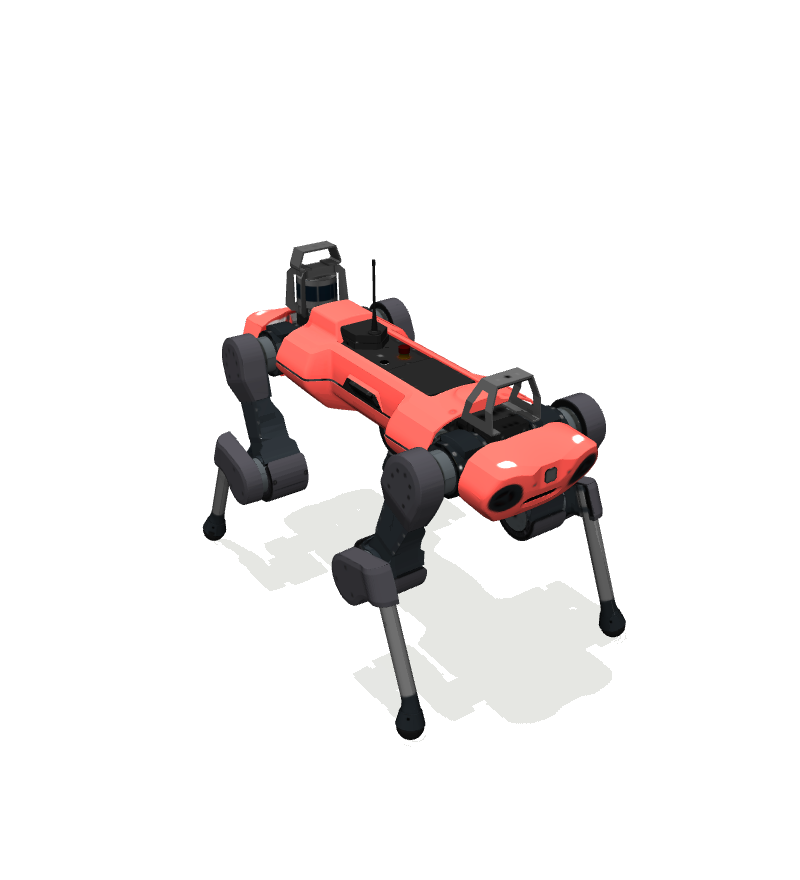
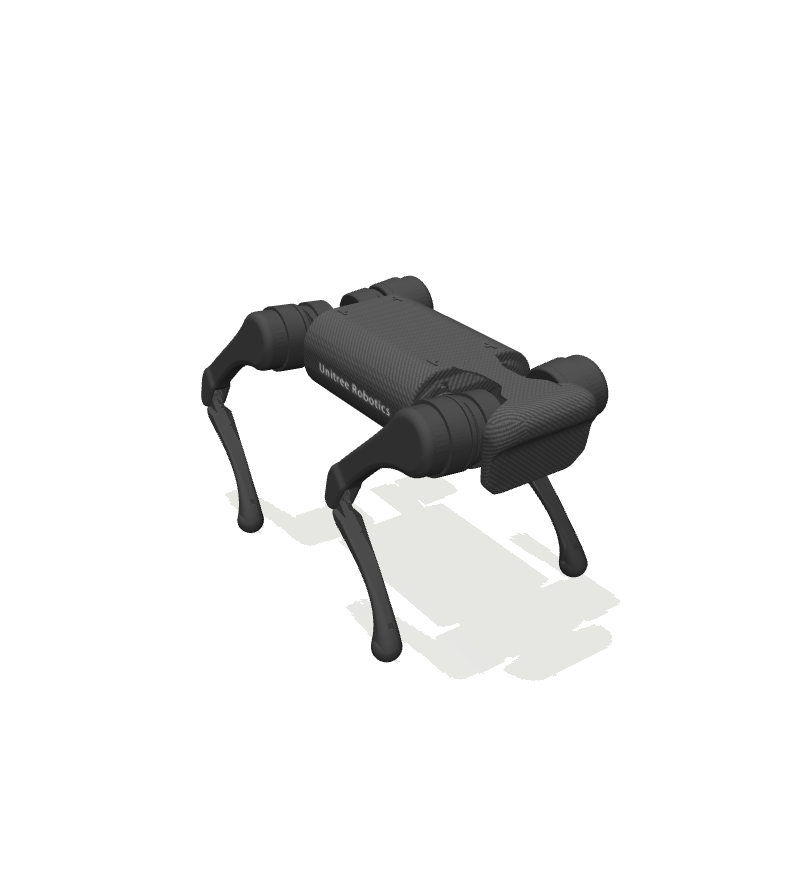
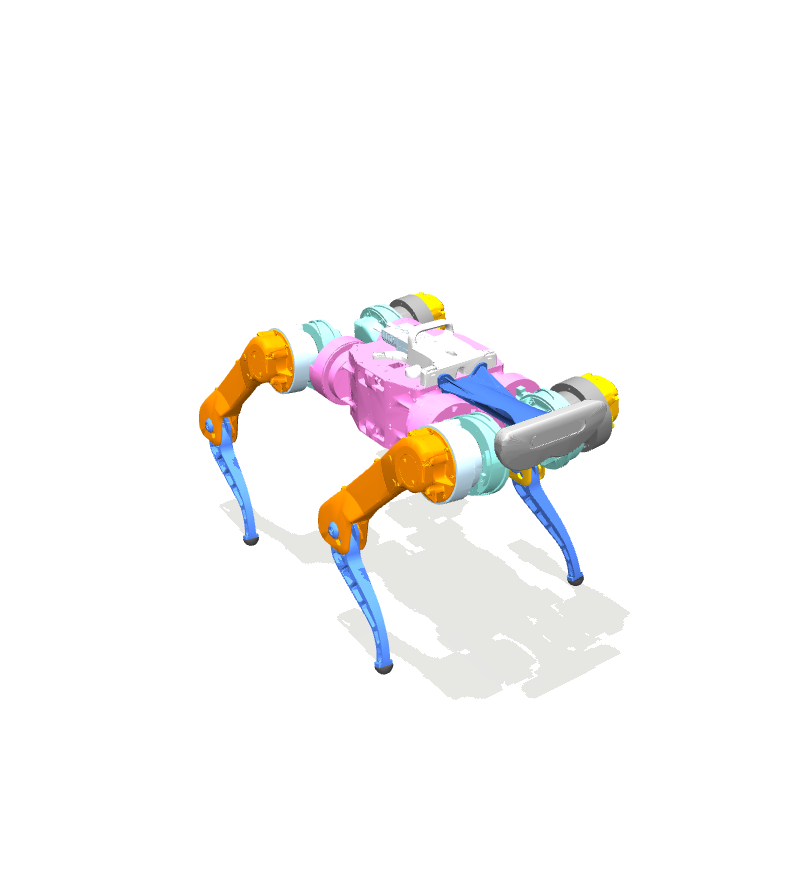
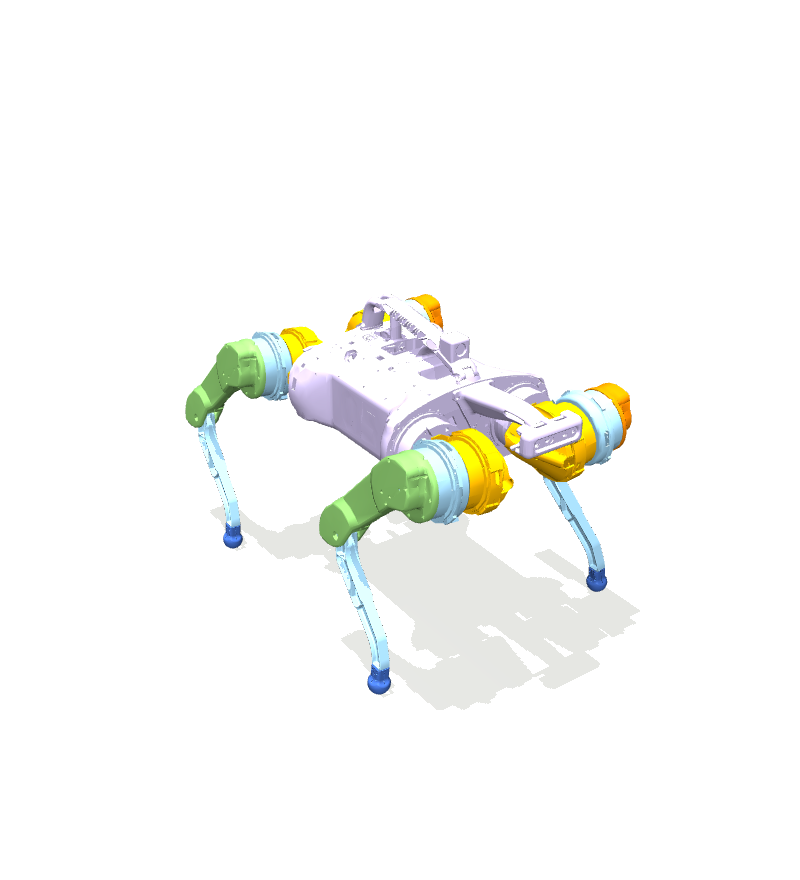
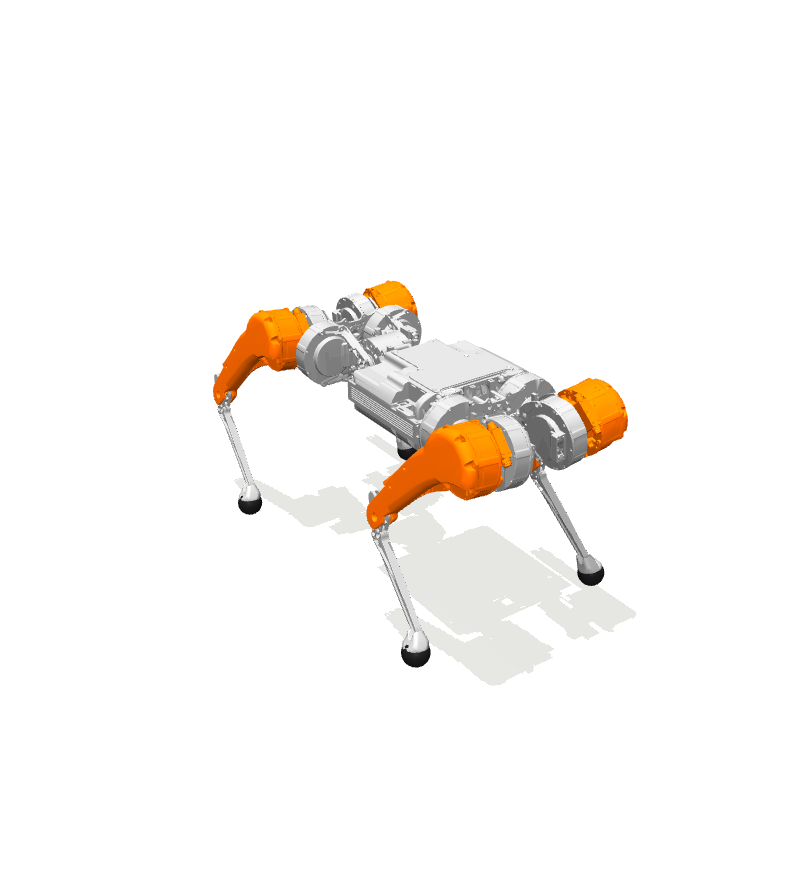
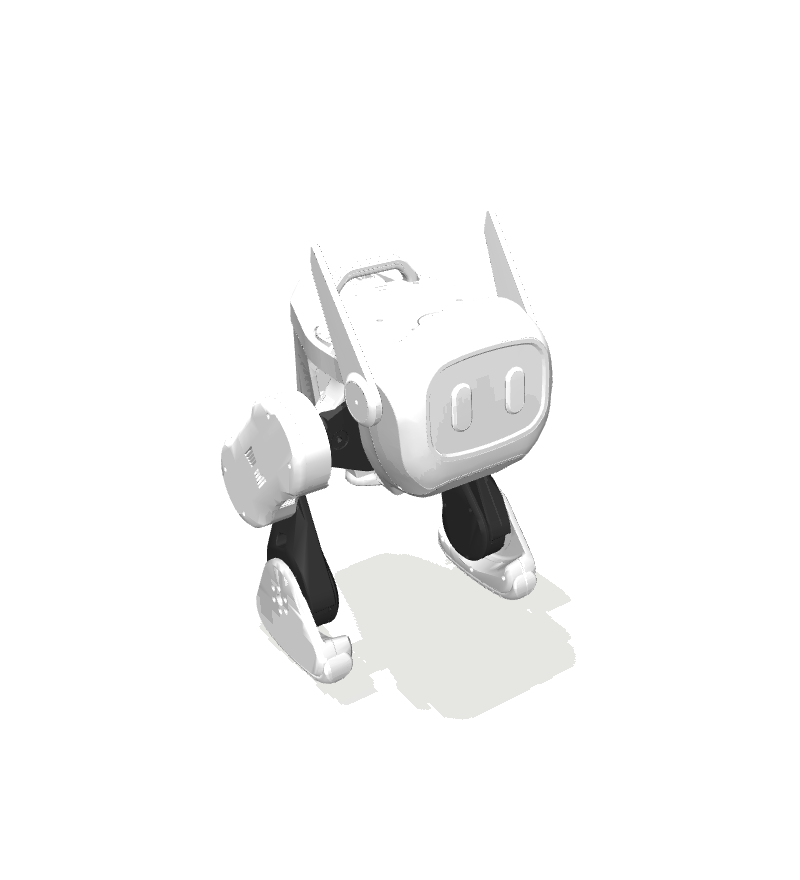
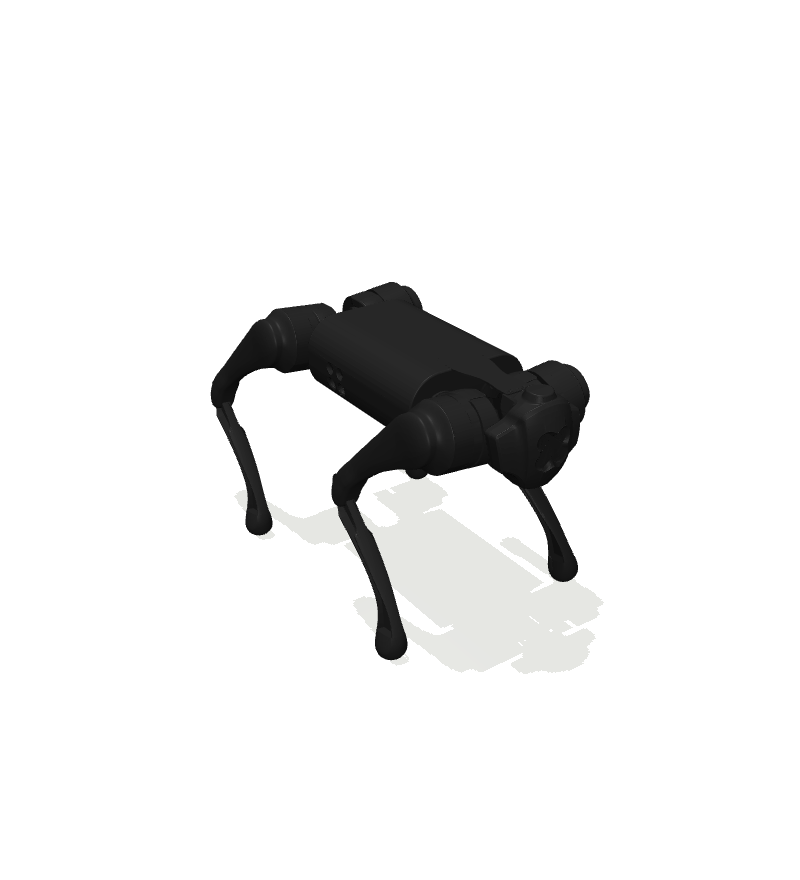
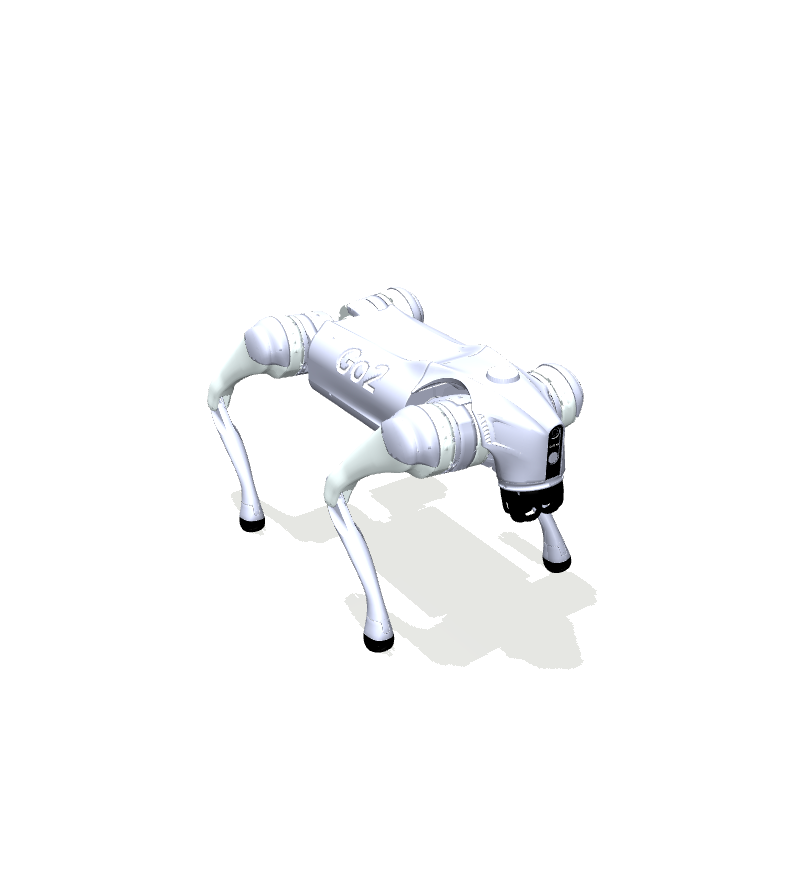
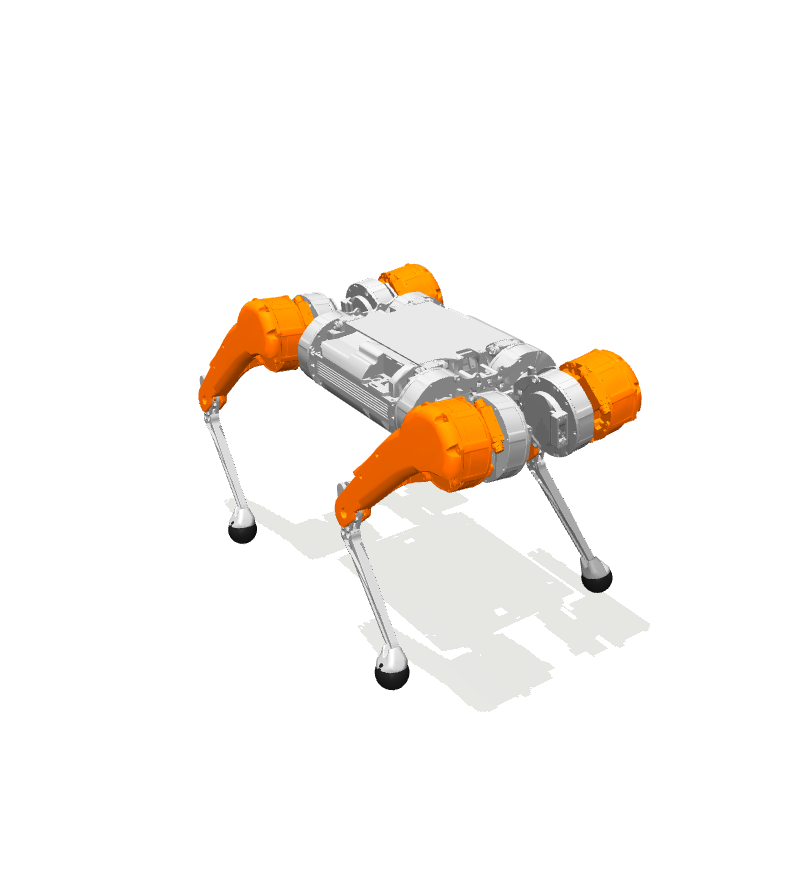
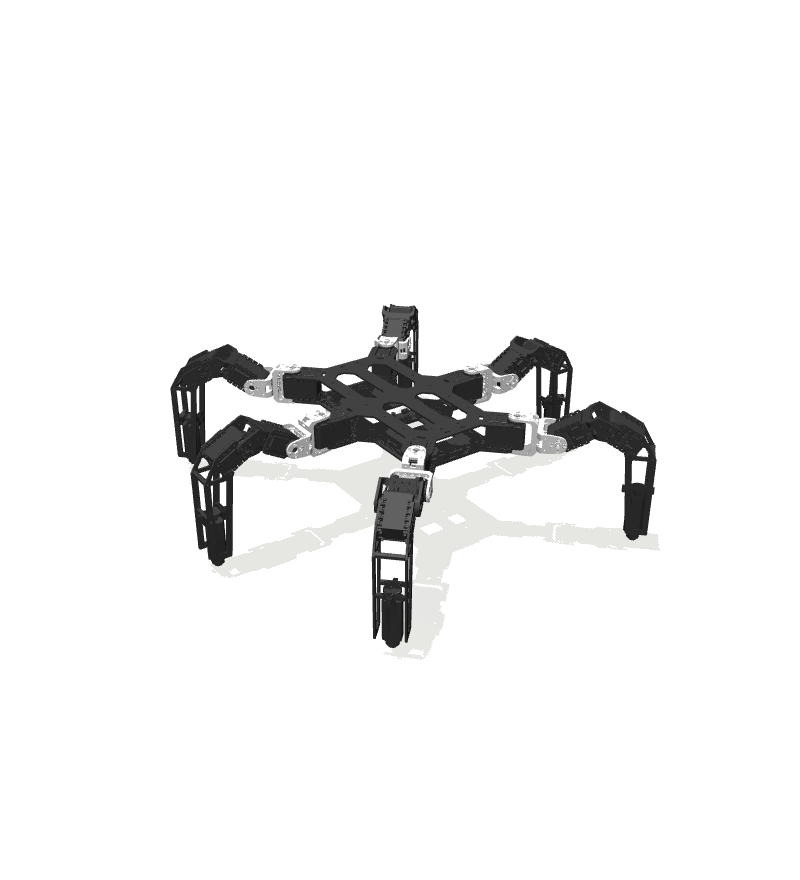
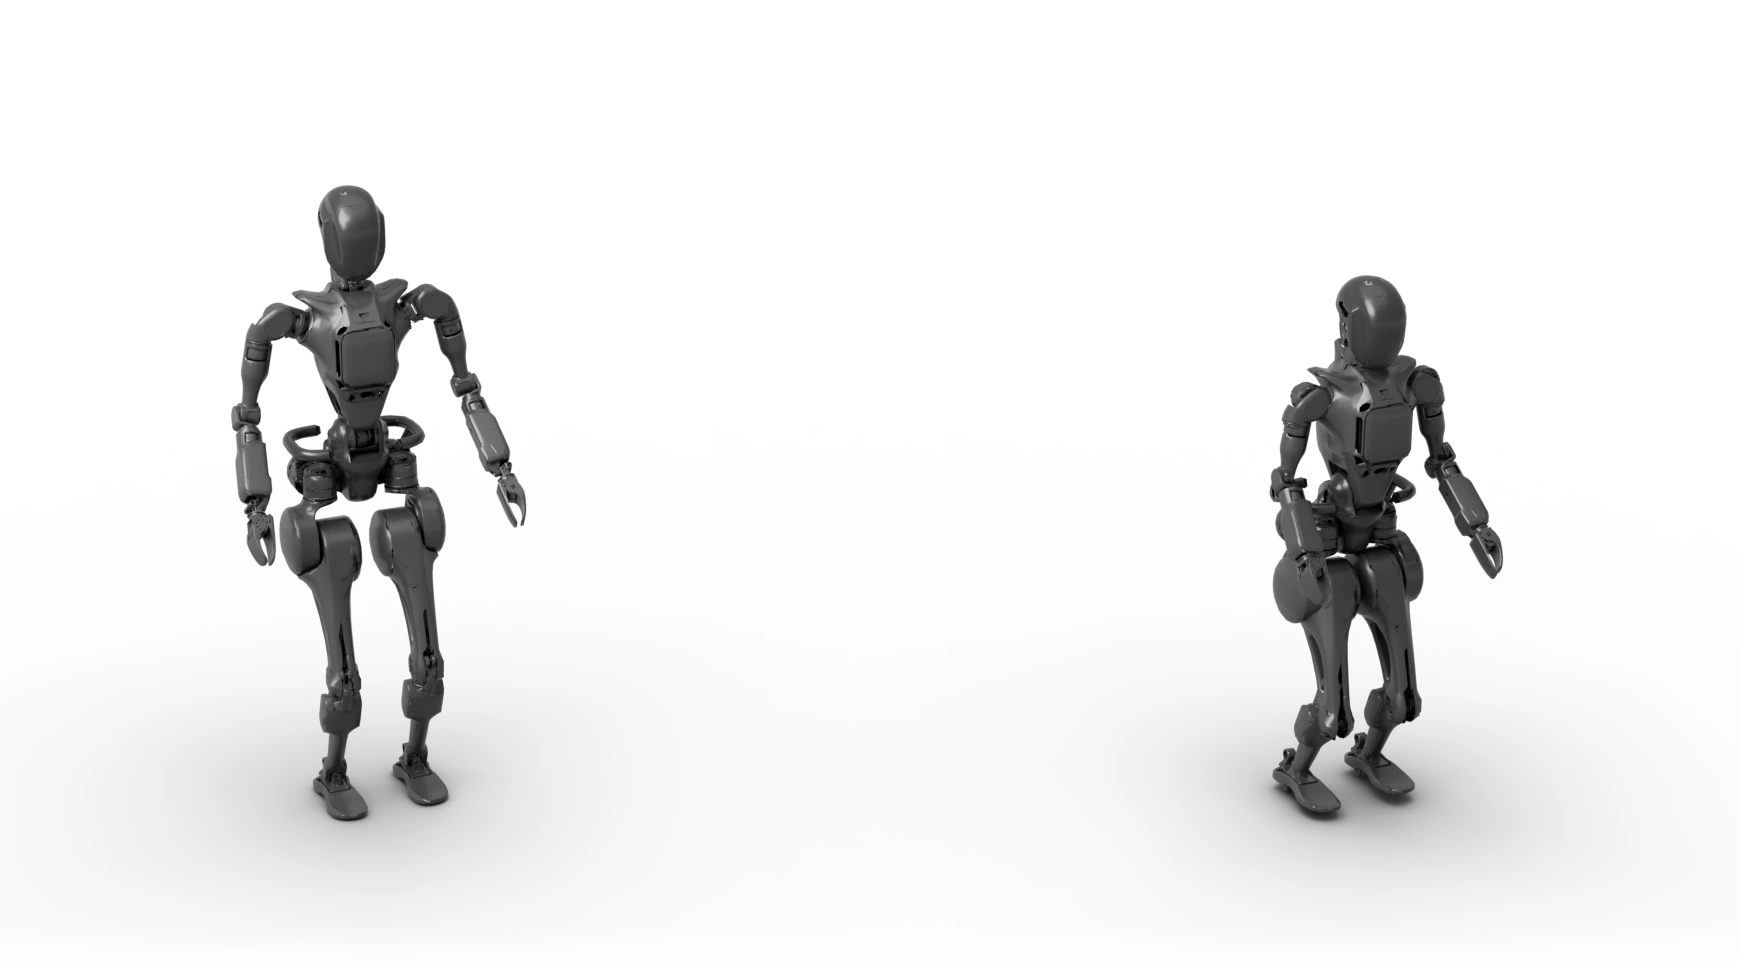
Choose a robot and inspect how Value-Gradient Design Search (VGDS) changes its embodiment. Reference is the nominal URDF, and Co-Design shows the optimized design from a perturbed start. Use the sliders to explore the designs and control the policy live.
Overview
Can a value function trained across many robots become a reusable design model? We train one embodiment-aware policy and value function across a broad robot distribution. After training, the value function is frozen and reused as a differentiable surrogate: new robots are optimized by following value gradients inside a soft trust region, over design spaces with more than 1100 parameters.

Value-Gradient Design Search
During training, each environment samples a robot design and keeps it fixed for the episode. A Unified Robot Morphology Architecture (URMA)-based policy and direct-design critic learn to control and evaluate the full design distribution with PPO.
After training, the policy and critic are frozen. We search for a design \(f\) that maximizes the mean value prediction over a fixed state bank, while remaining in a trust region around \(f_{\mathrm{ref}}\):
Relaxing this constraint gives the penalized objective used by VGDS and the search baselines:
VGDS improves the design by following this objective's gradients through the frozen value function and the design map \(\Phi\). The soft trust-region penalty limits unreliable extrapolation, and normalization by \(d_{\mathrm{design}}\) makes its strength comparable across robots with different design dimensions.
This gives a design loop based on one trained model that can be batched and reused for many robots.
Multi-Embodiment Training Set
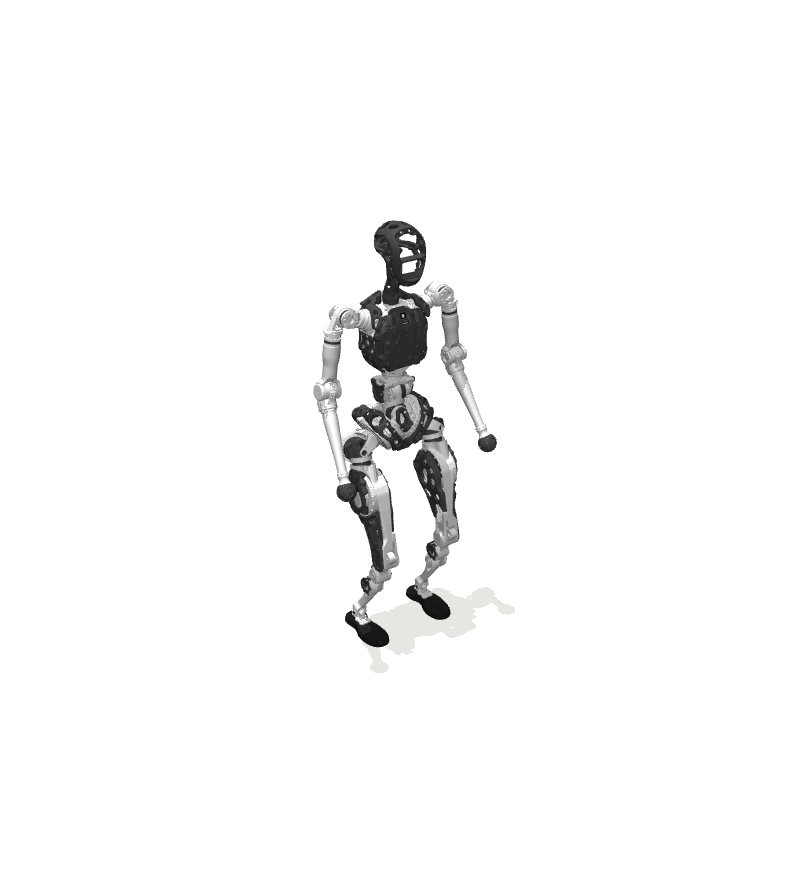
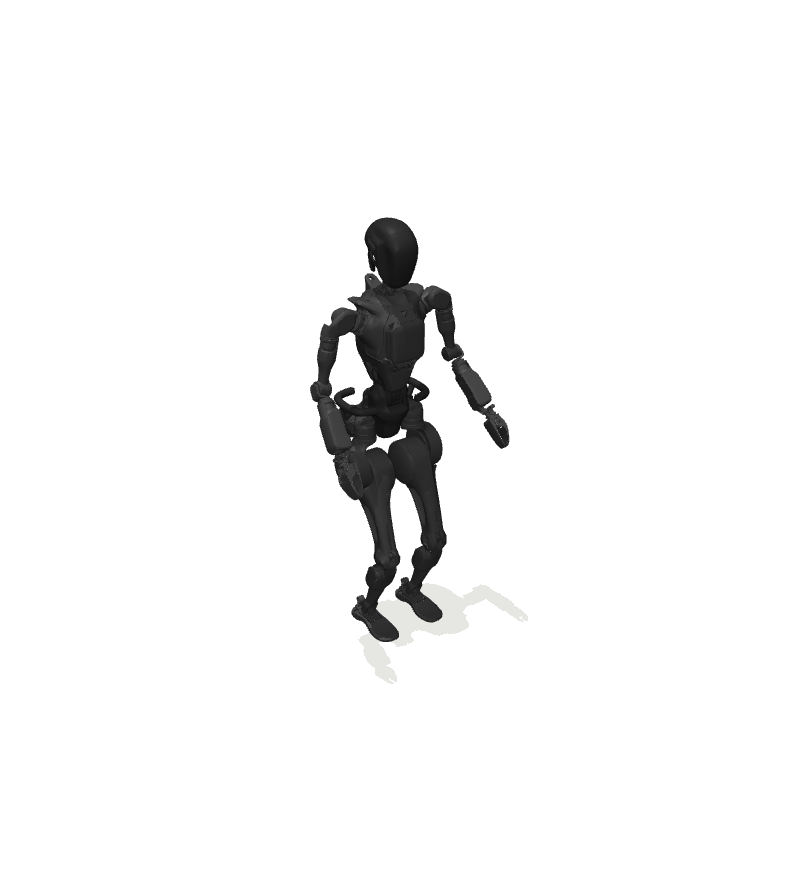
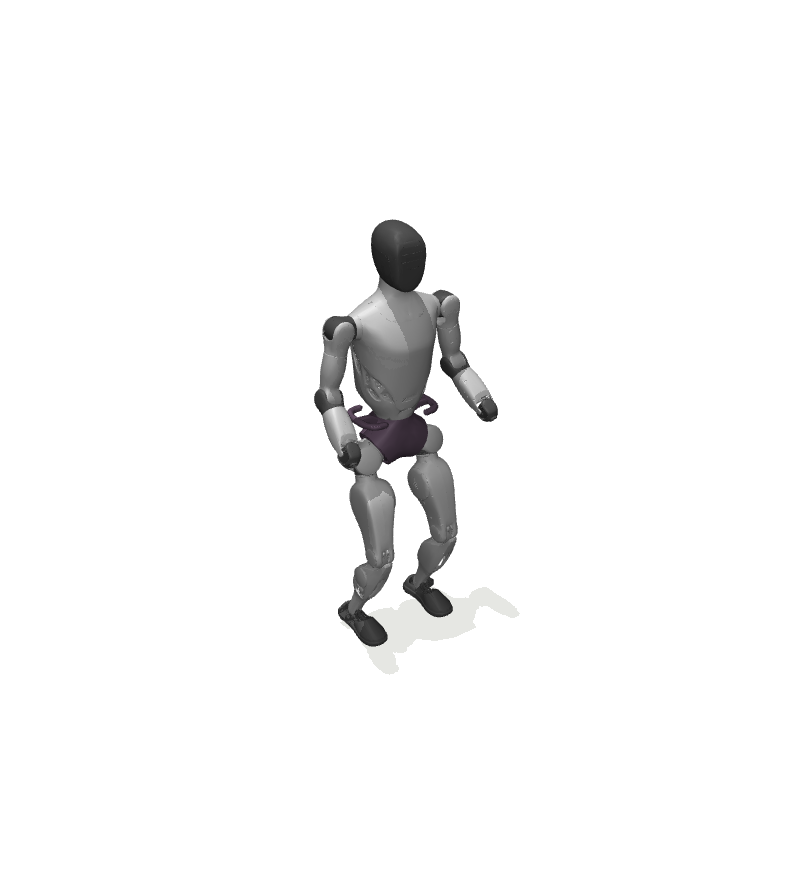
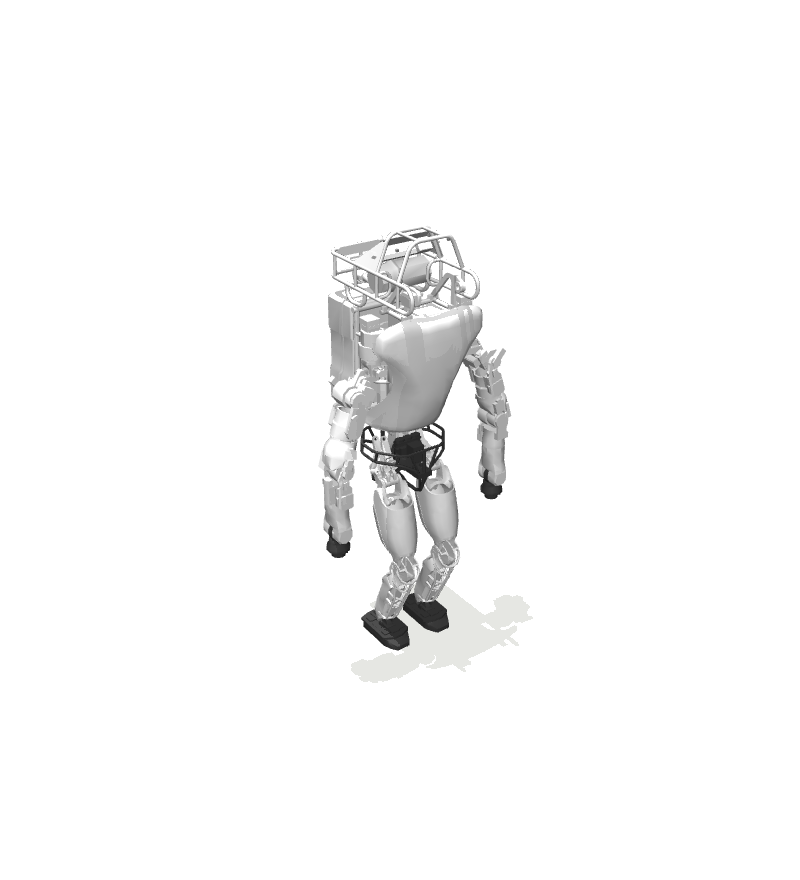
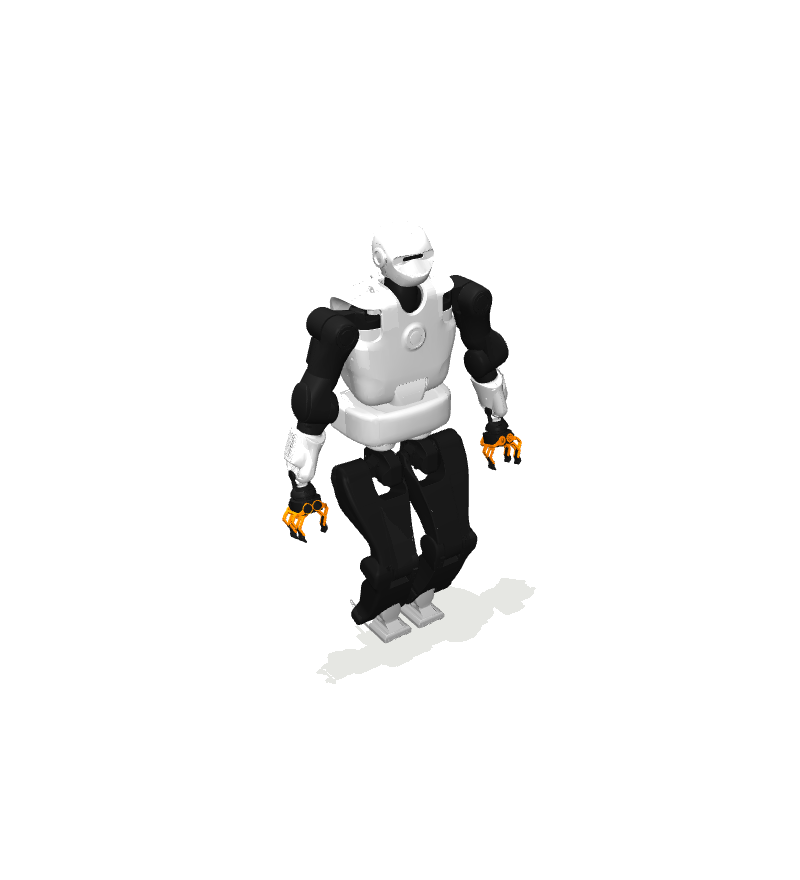
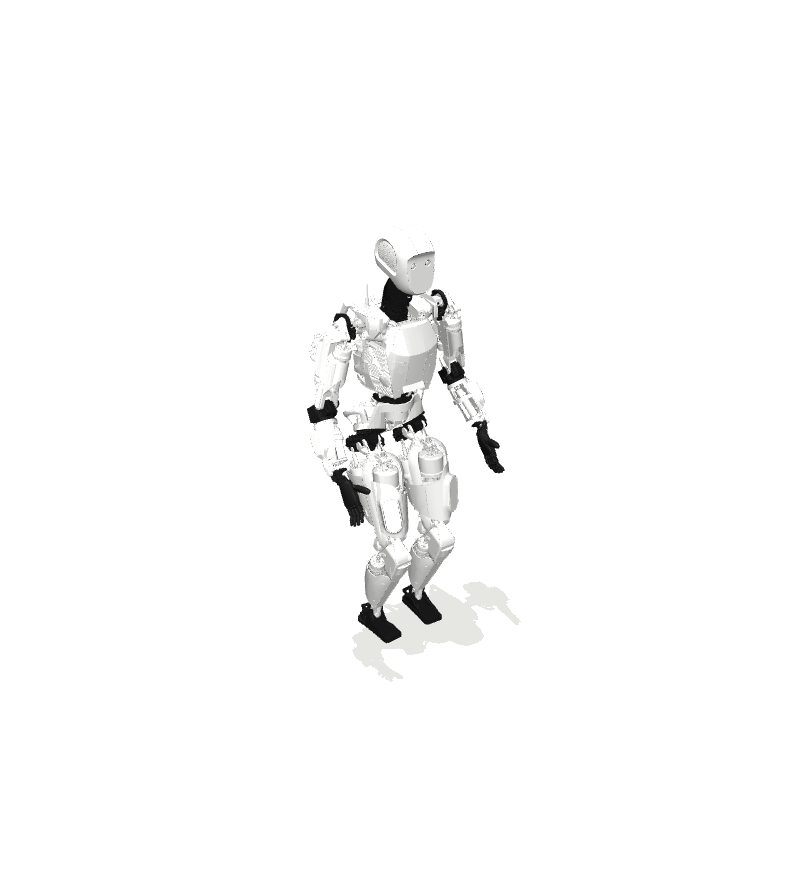
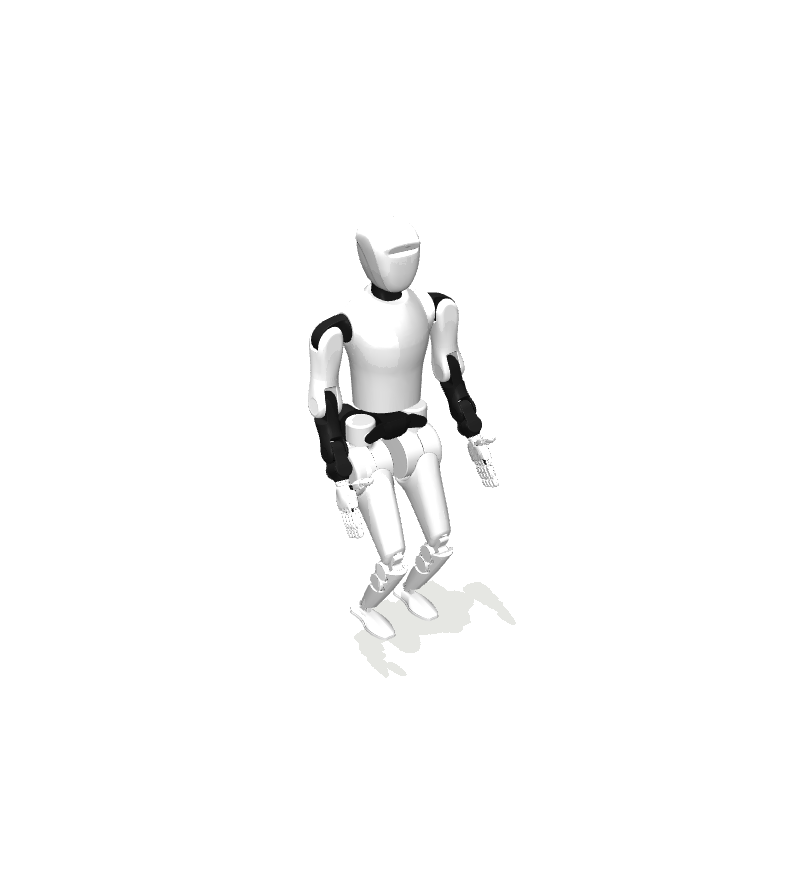
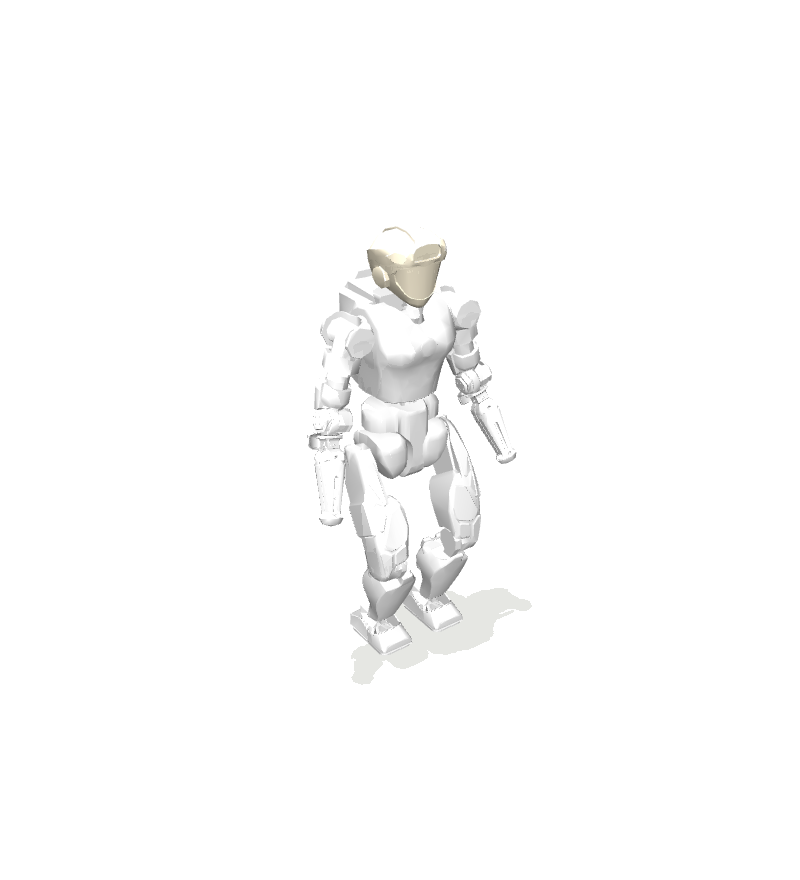
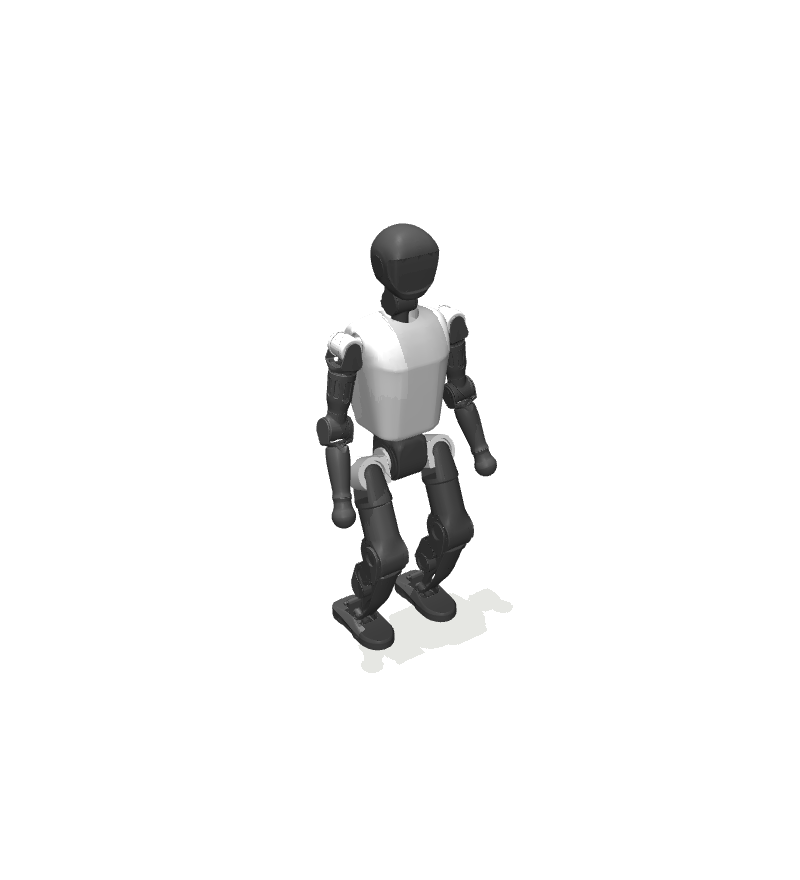
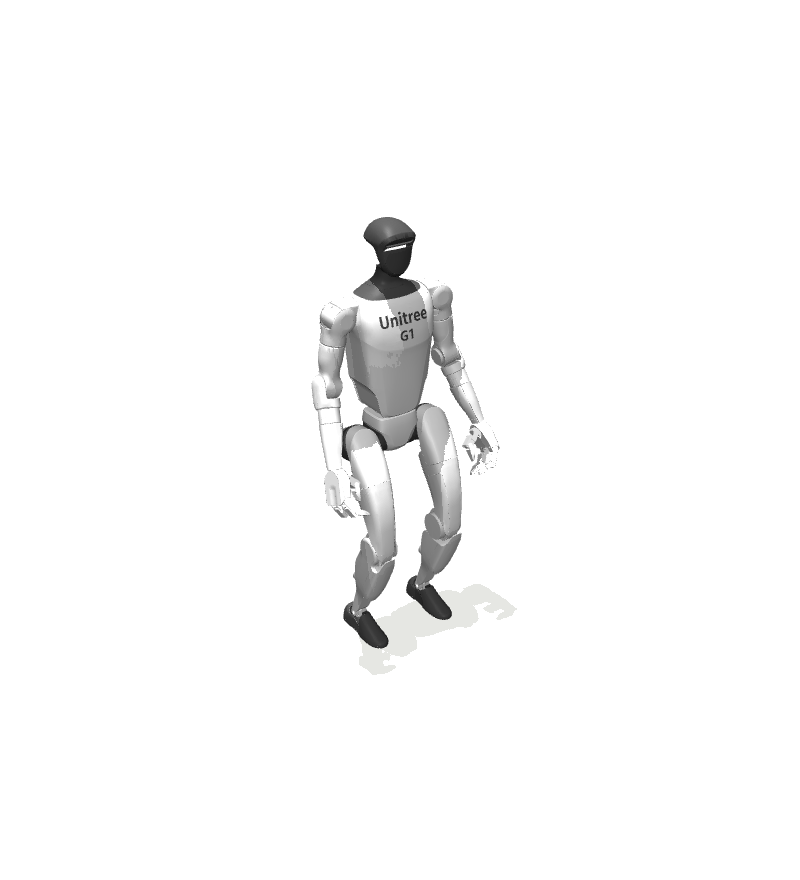
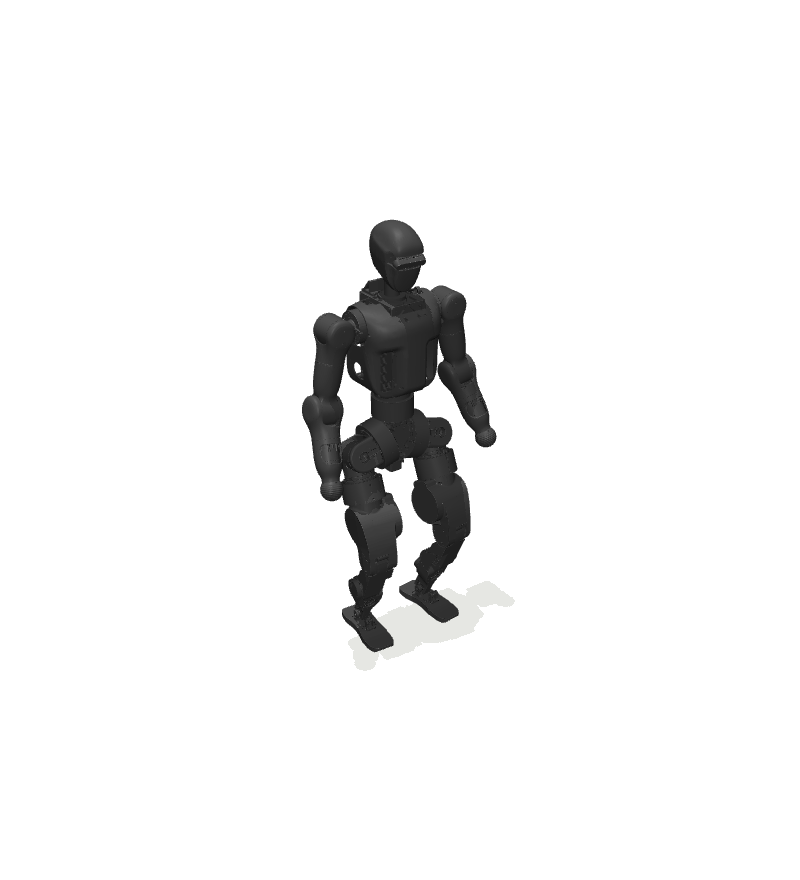
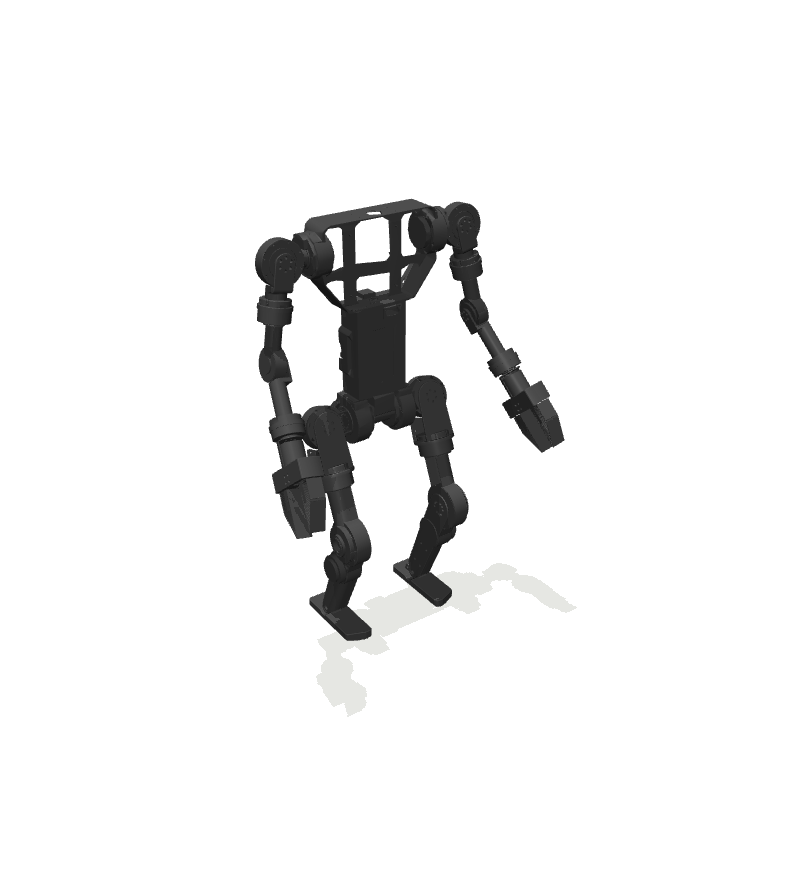
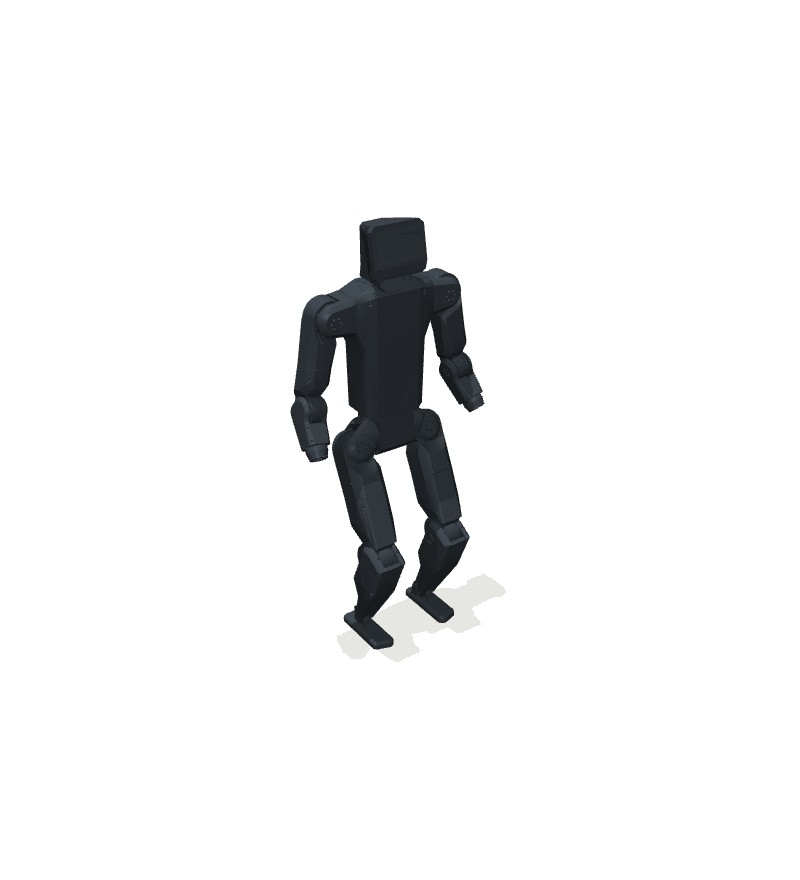
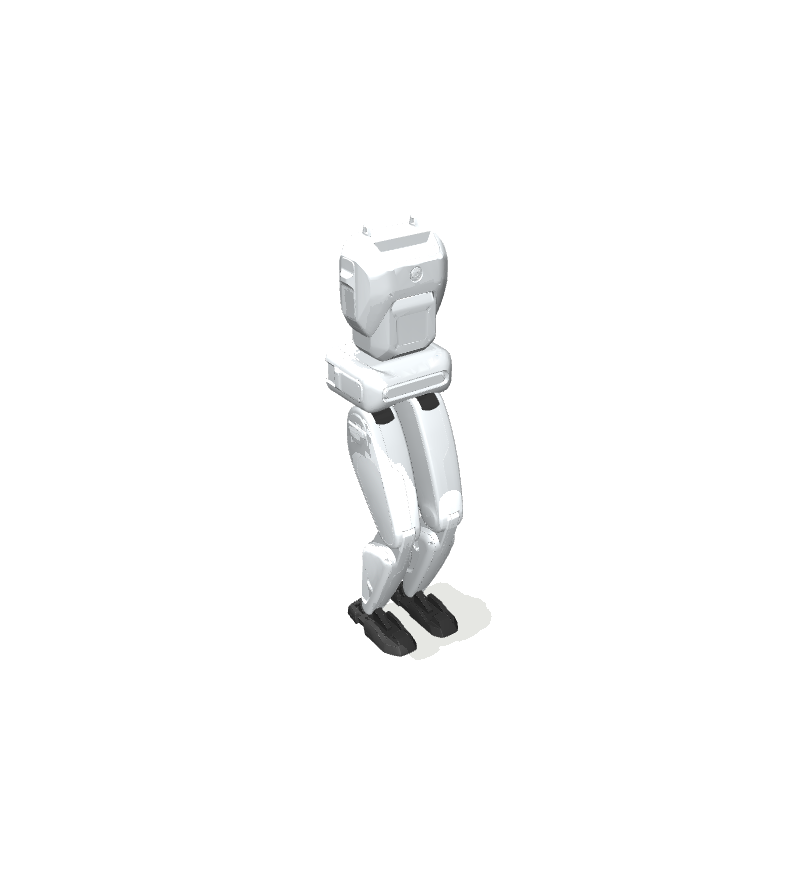
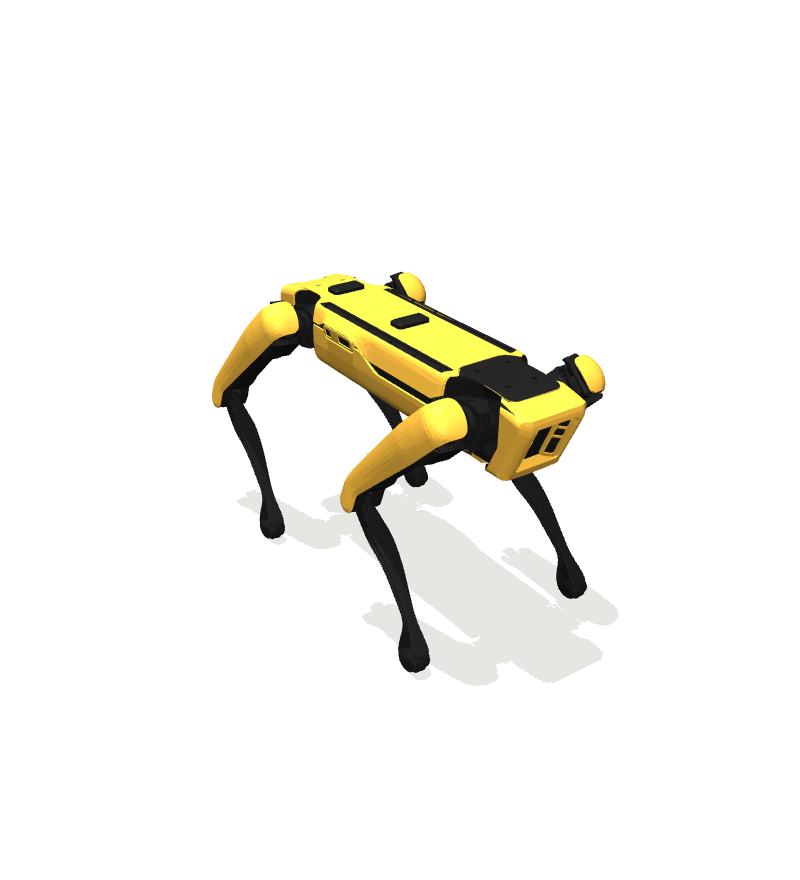
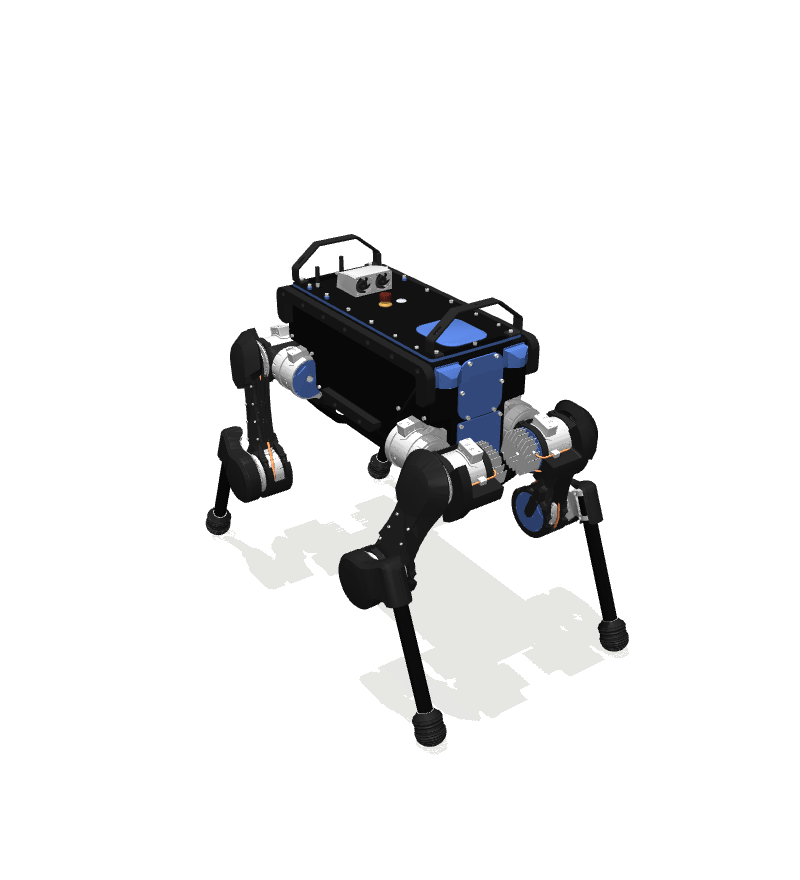
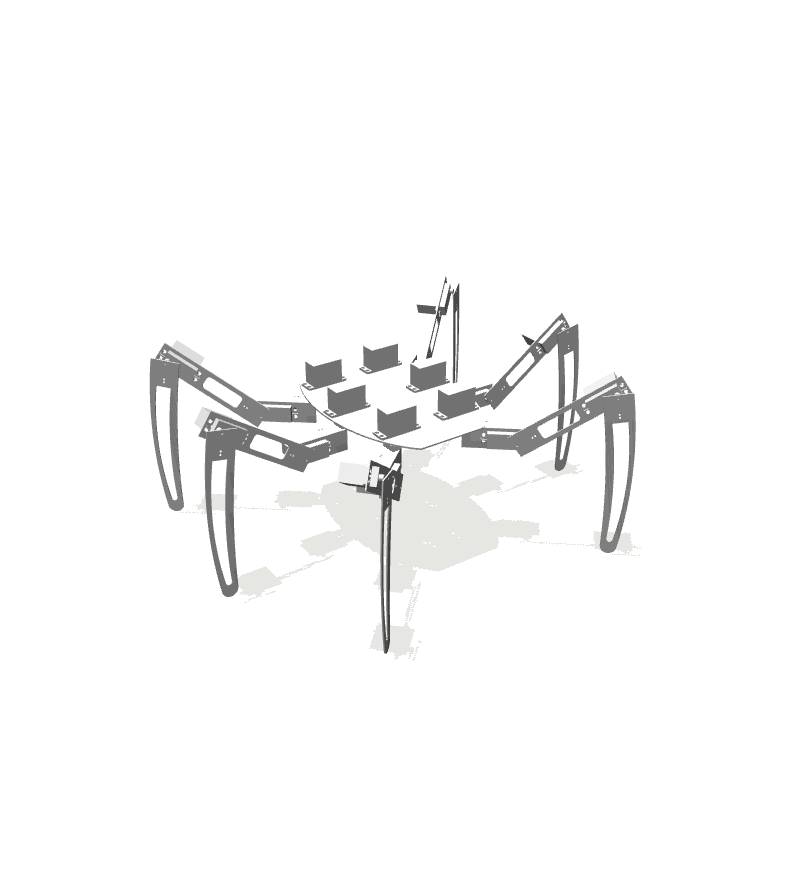
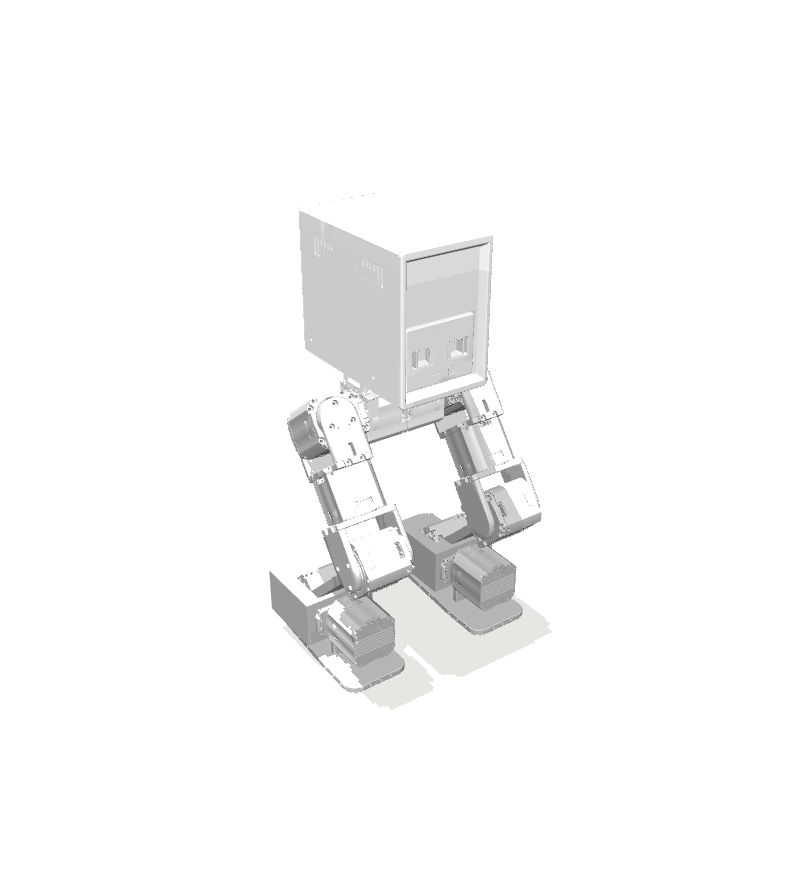
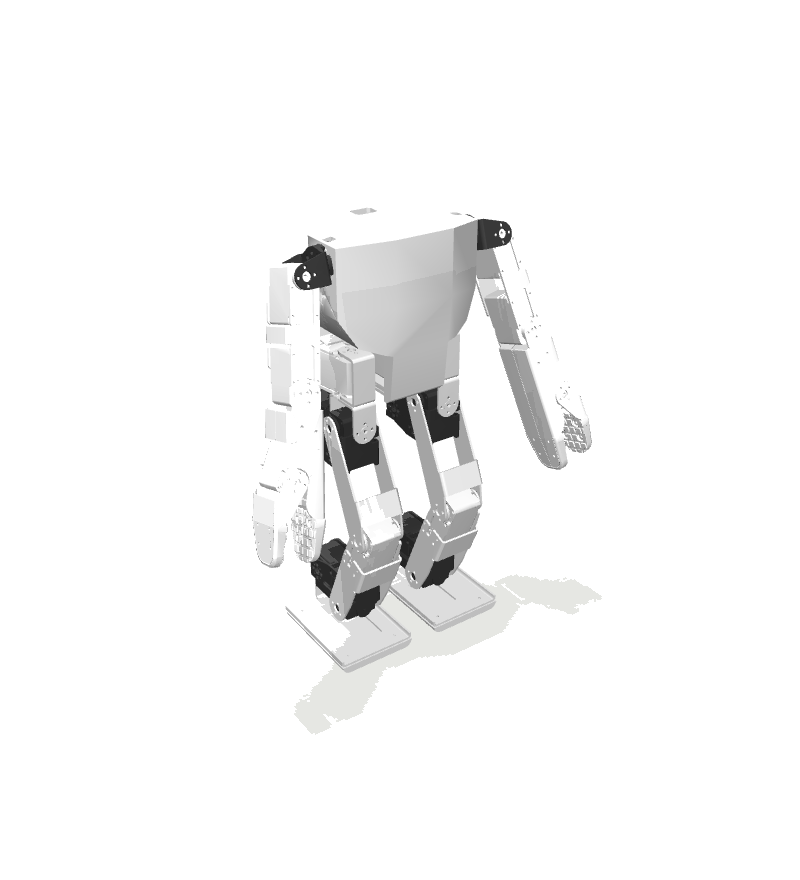
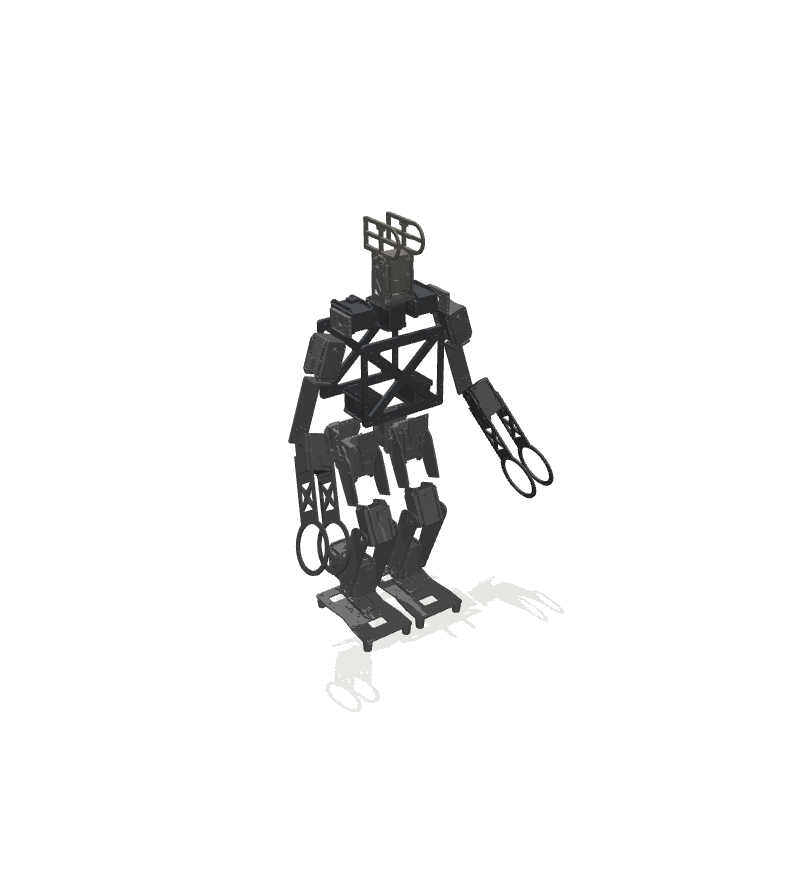
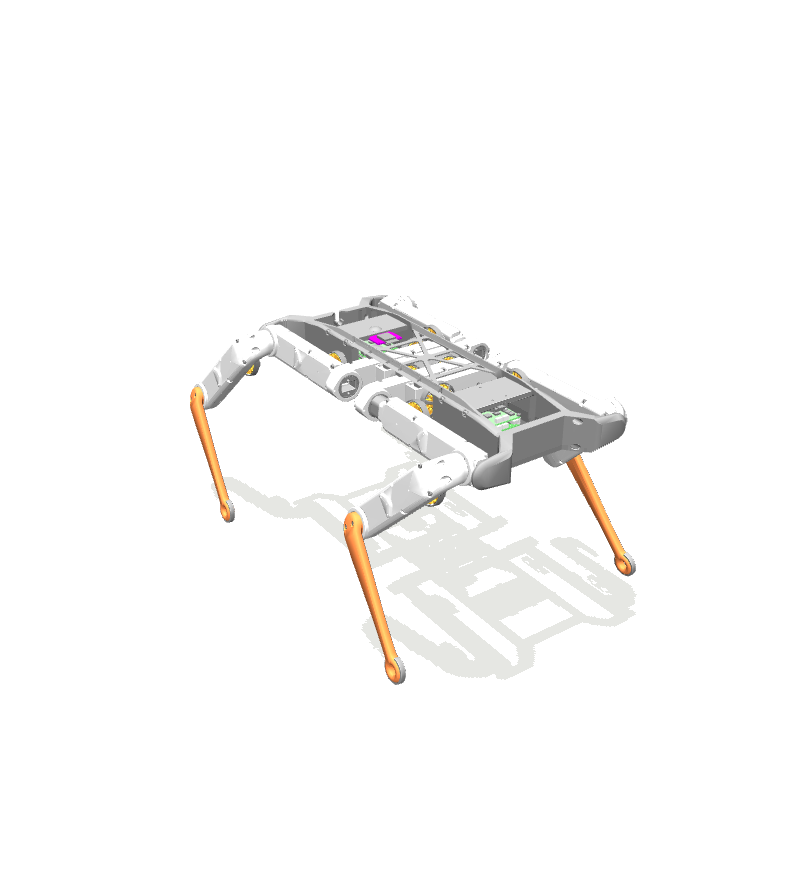
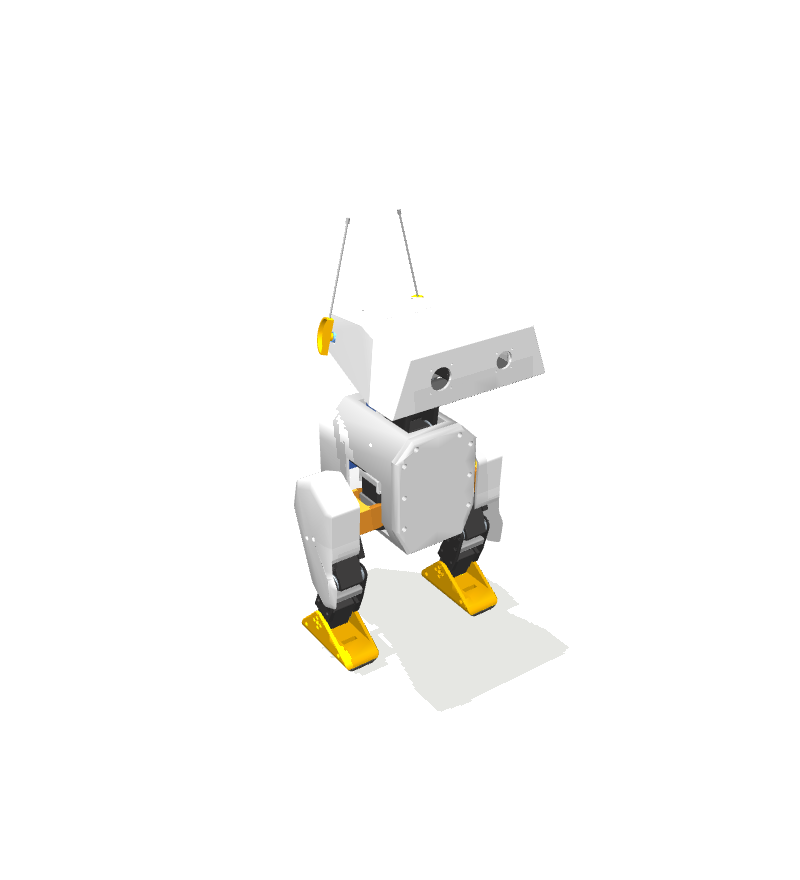
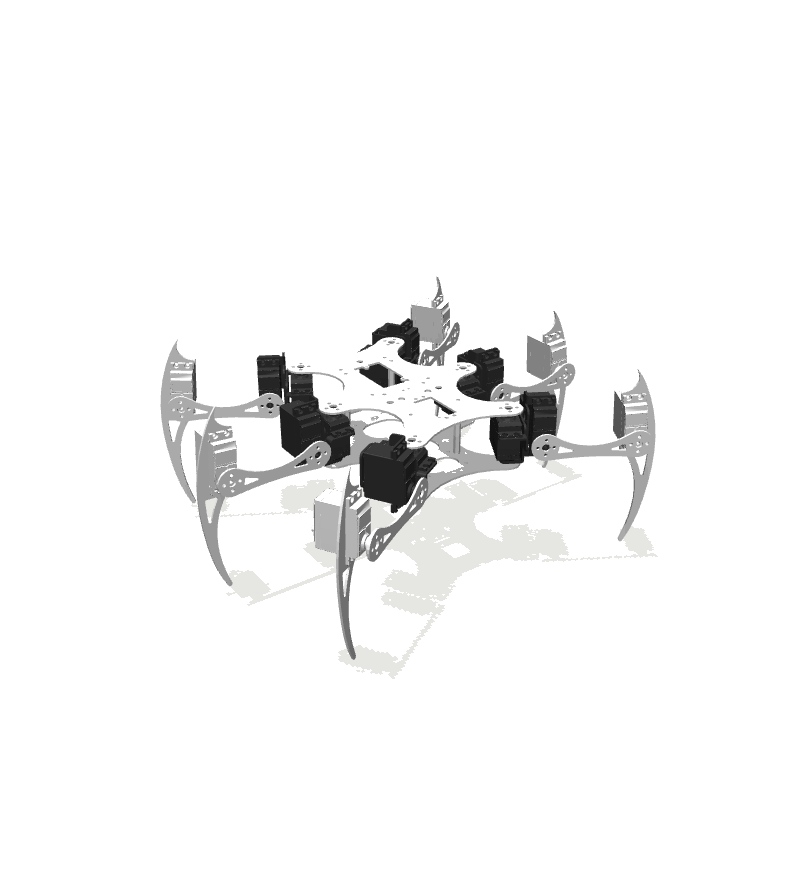
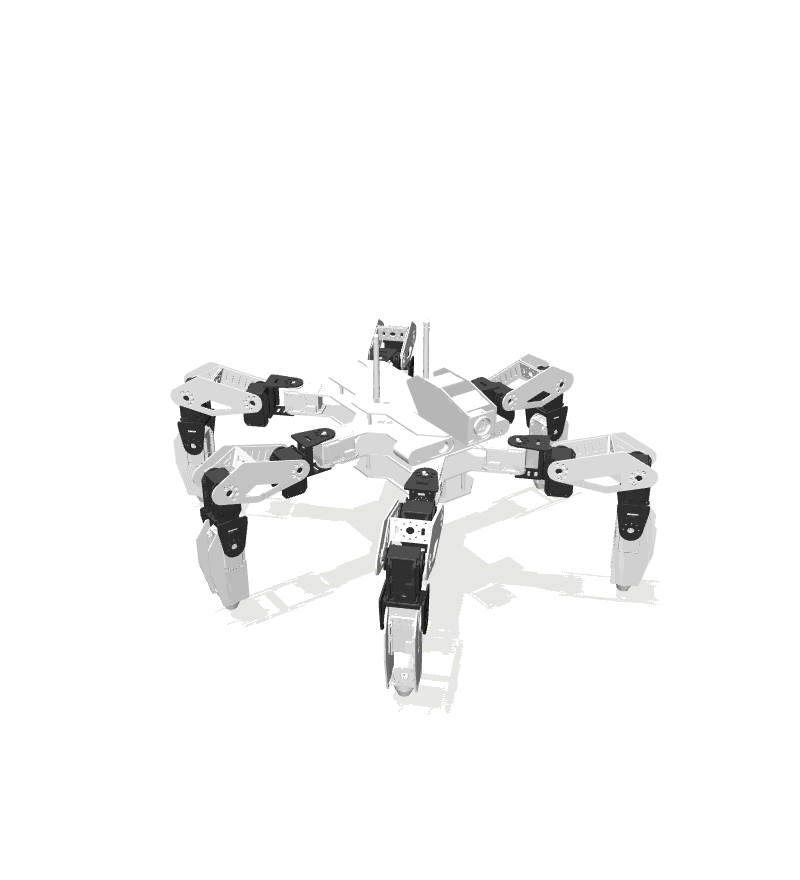
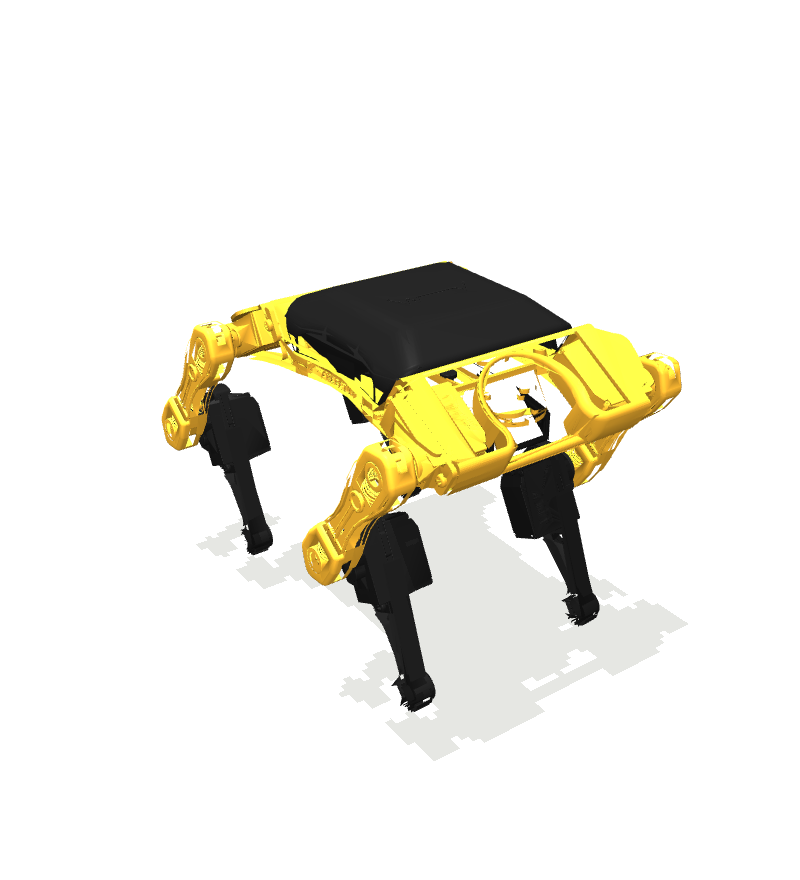
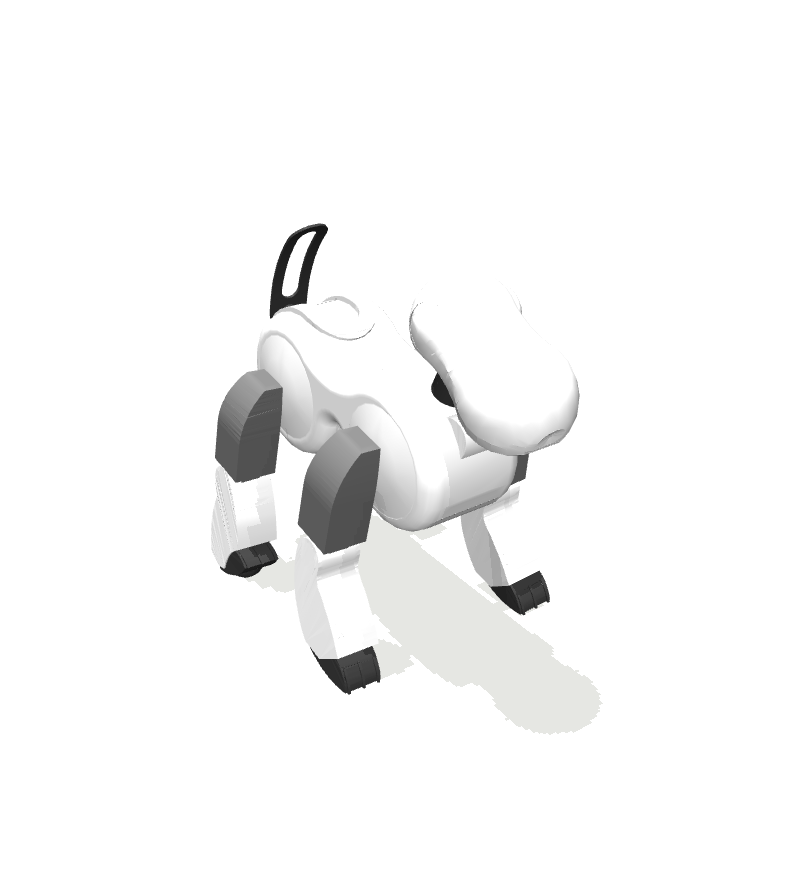
Our largest training set contains 50 robots: 15 quadrupeds, 31 bipeds and humanoids, and 4 hexapods. One URMA policy and critic are trained across all of them, with randomization over masses, inertias, geometry, joint limits, PD gains, and actuator properties. Each robot has 190 to 1177 continuous design parameters.
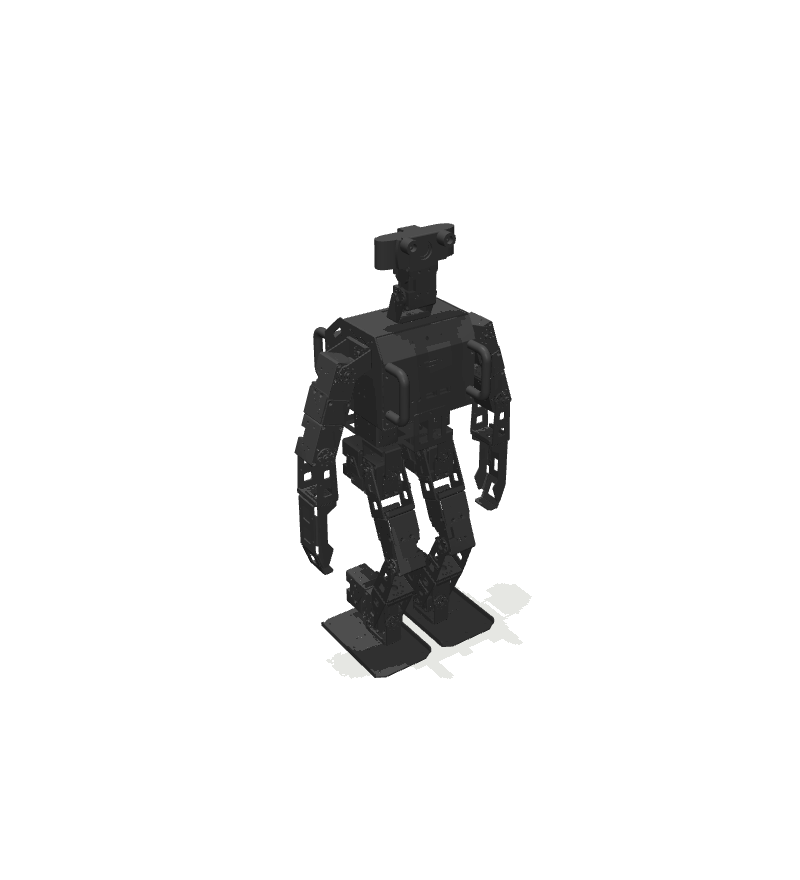
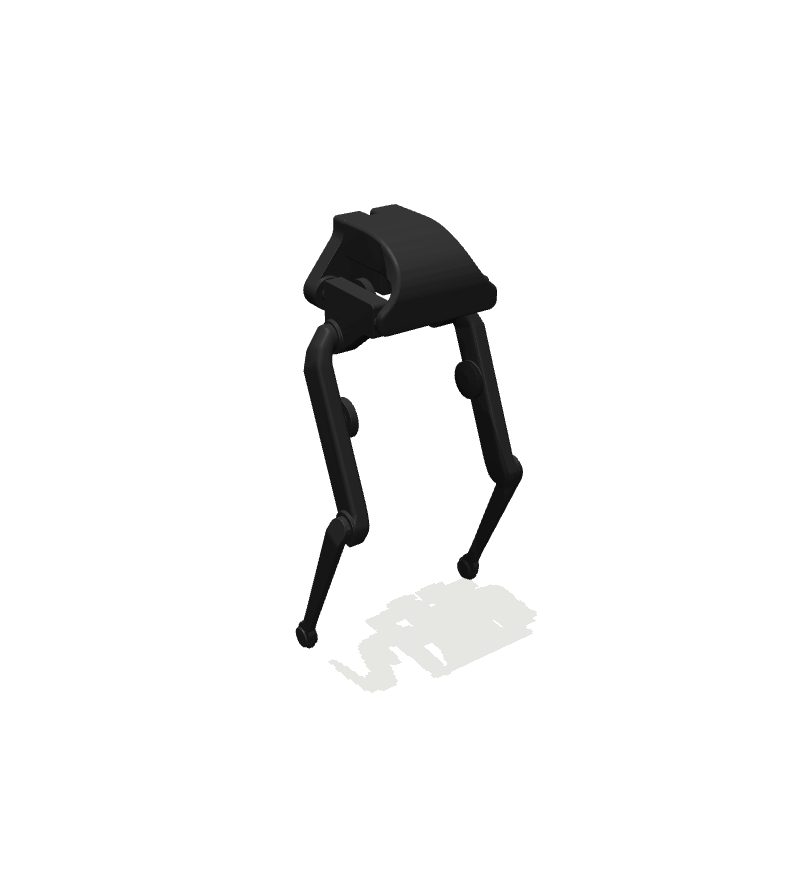
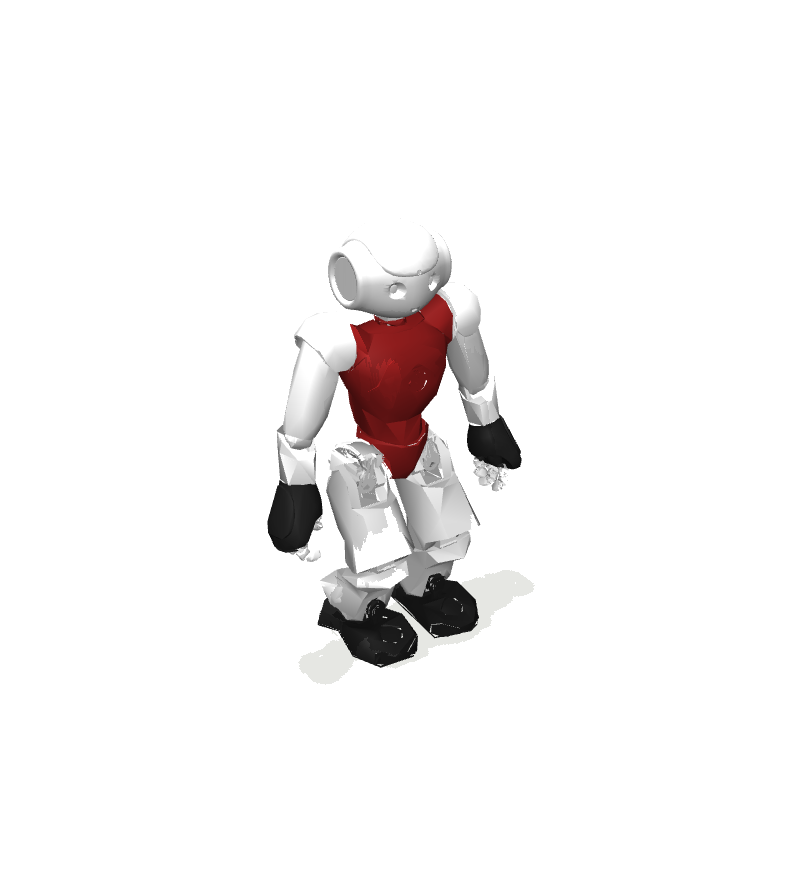
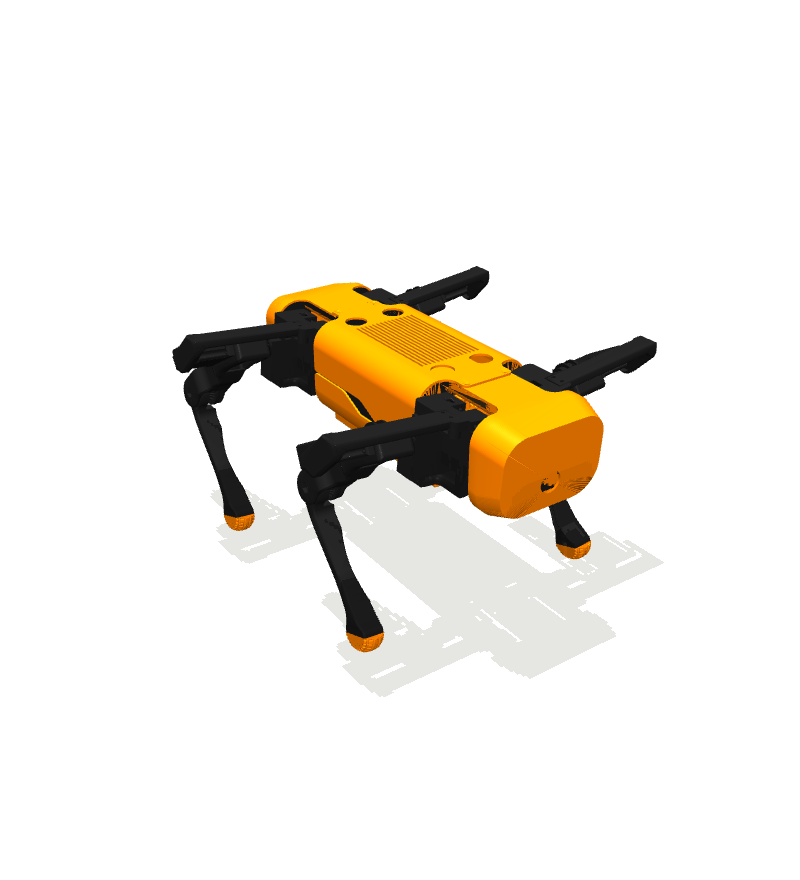
Single-Robot Design
First, we train one policy and critic per target robot, then optimize perturbed designs of that same robot. Across the Unitree Go2 quadruped, MIT Humanoid, and Golem hexapod, VGDS matches or outperforms strong surrogate-search baselines, including BO, CMA-ES, PSO, CEM, DE, ARS, TuRBO, and GC-PFO.
Against adapted RL-based co-design baselines, VGDS reaches similar or slightly better final return. The main difference is cost: RL baselines train a new policy for every initial design, while VGDS trains once. After one 7–9 hour training run, each additional design takes only 1–2 minutes of search.
Generalization Across Robots
We then train reusable policies and critics on morphology-class robot sets, with the target robot held out, and on the full 50-robot set. With all 50 robots, VGDS improves beyond the nominal URDF for Unitree Go2 and MIT Humanoid and Golem. For Golem, the hexapod-only model performs best, likely because the full 50-robot set is dominated by quadrupeds and bipeds.
Optimized Designs
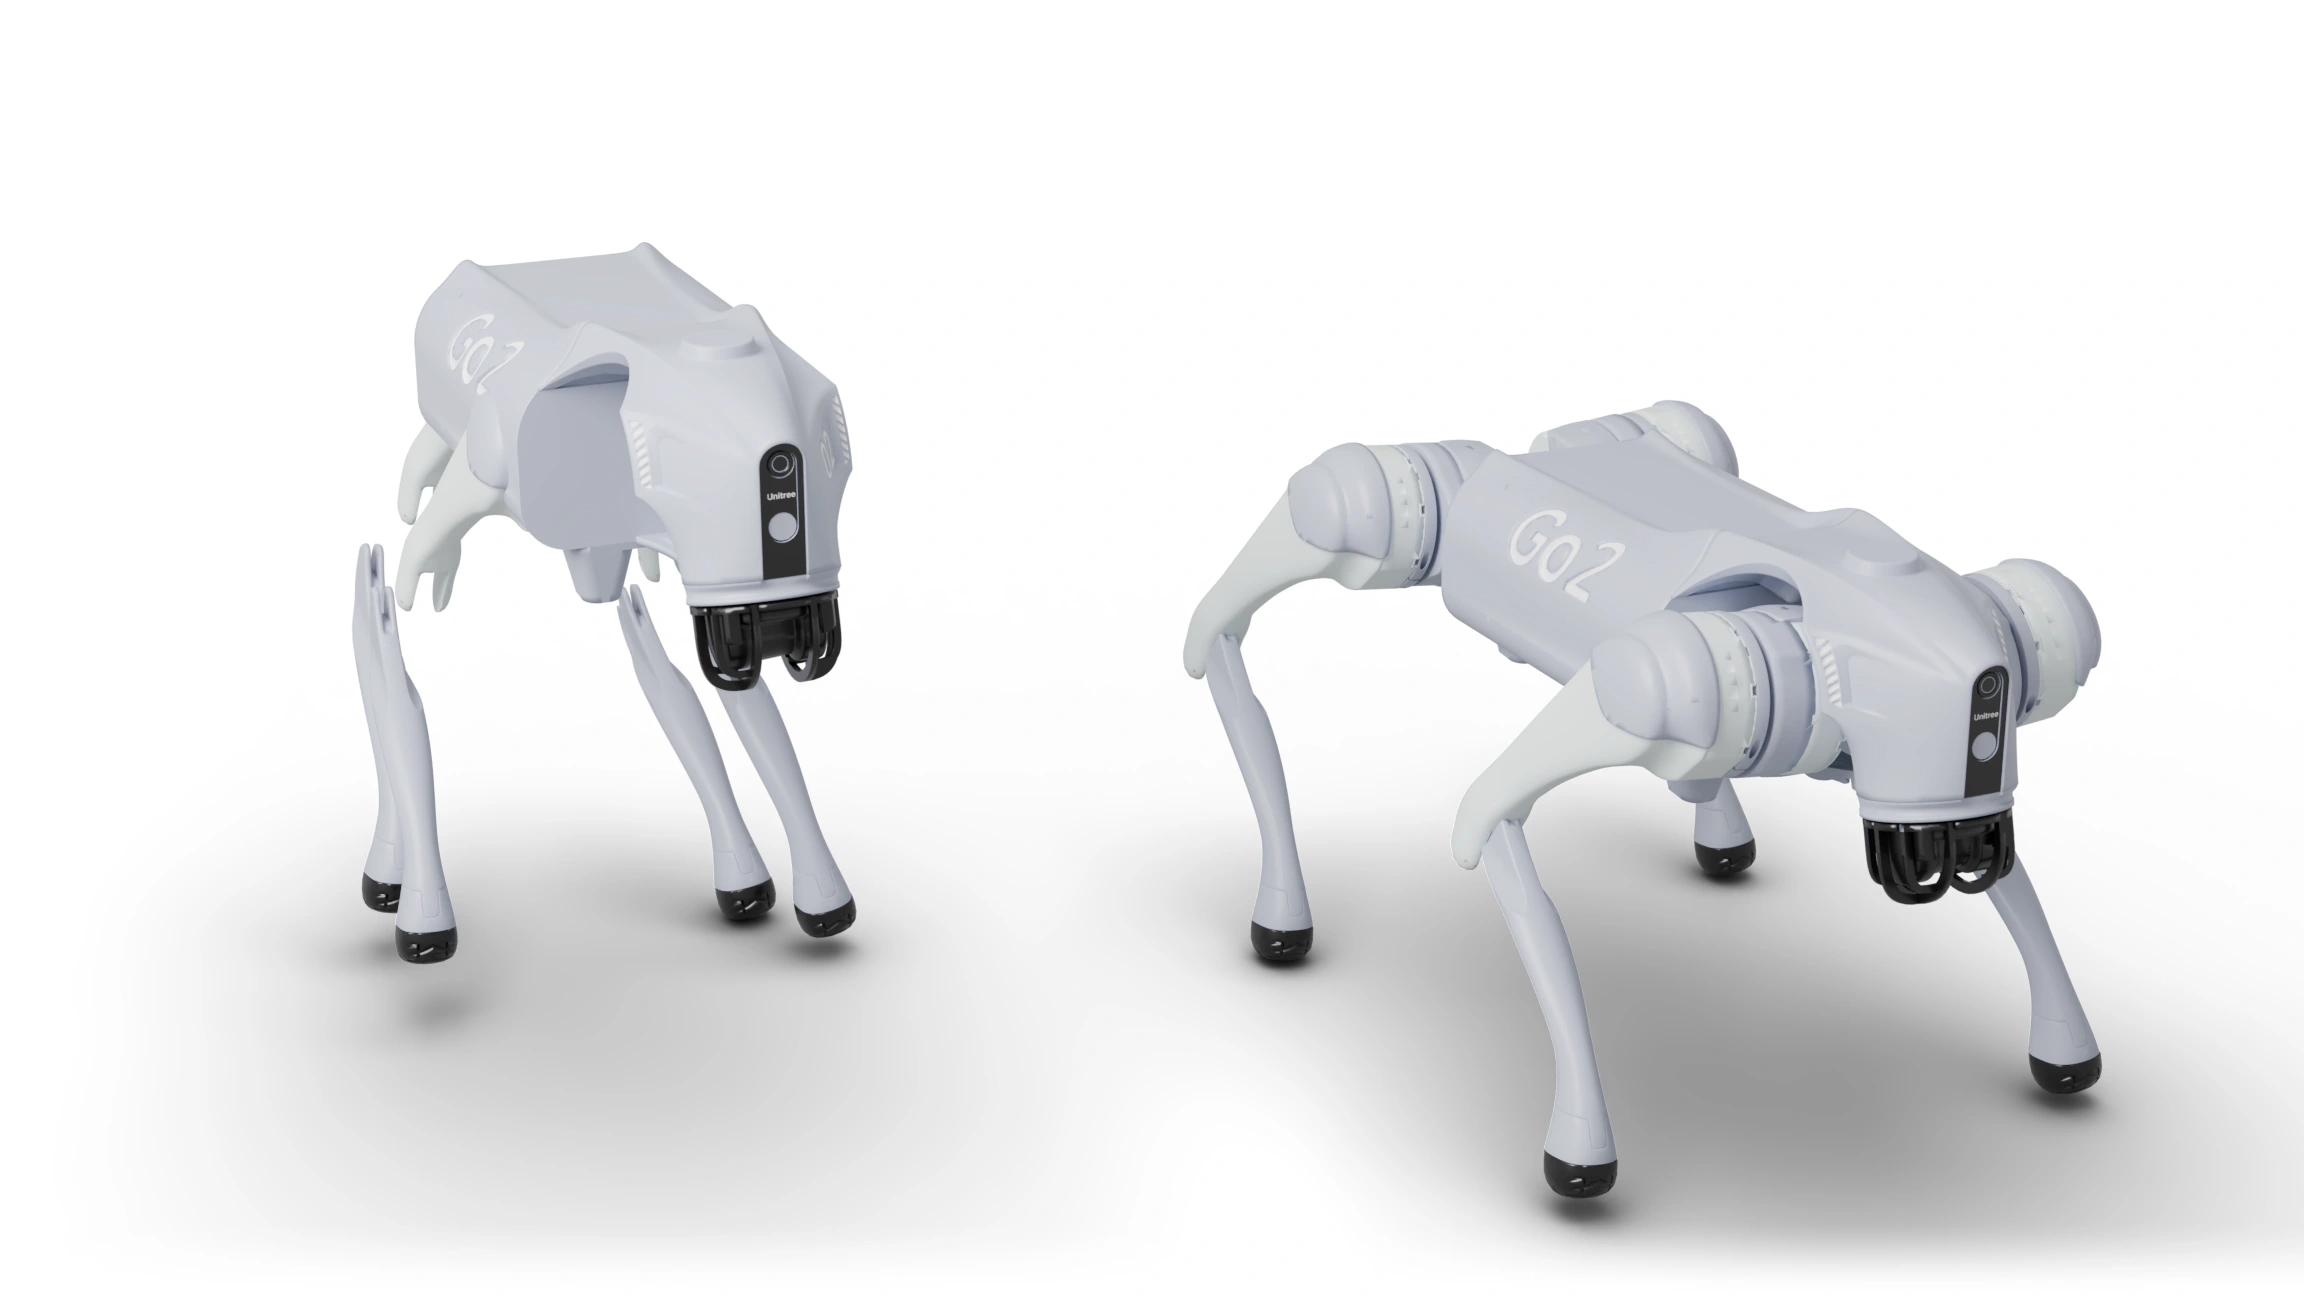
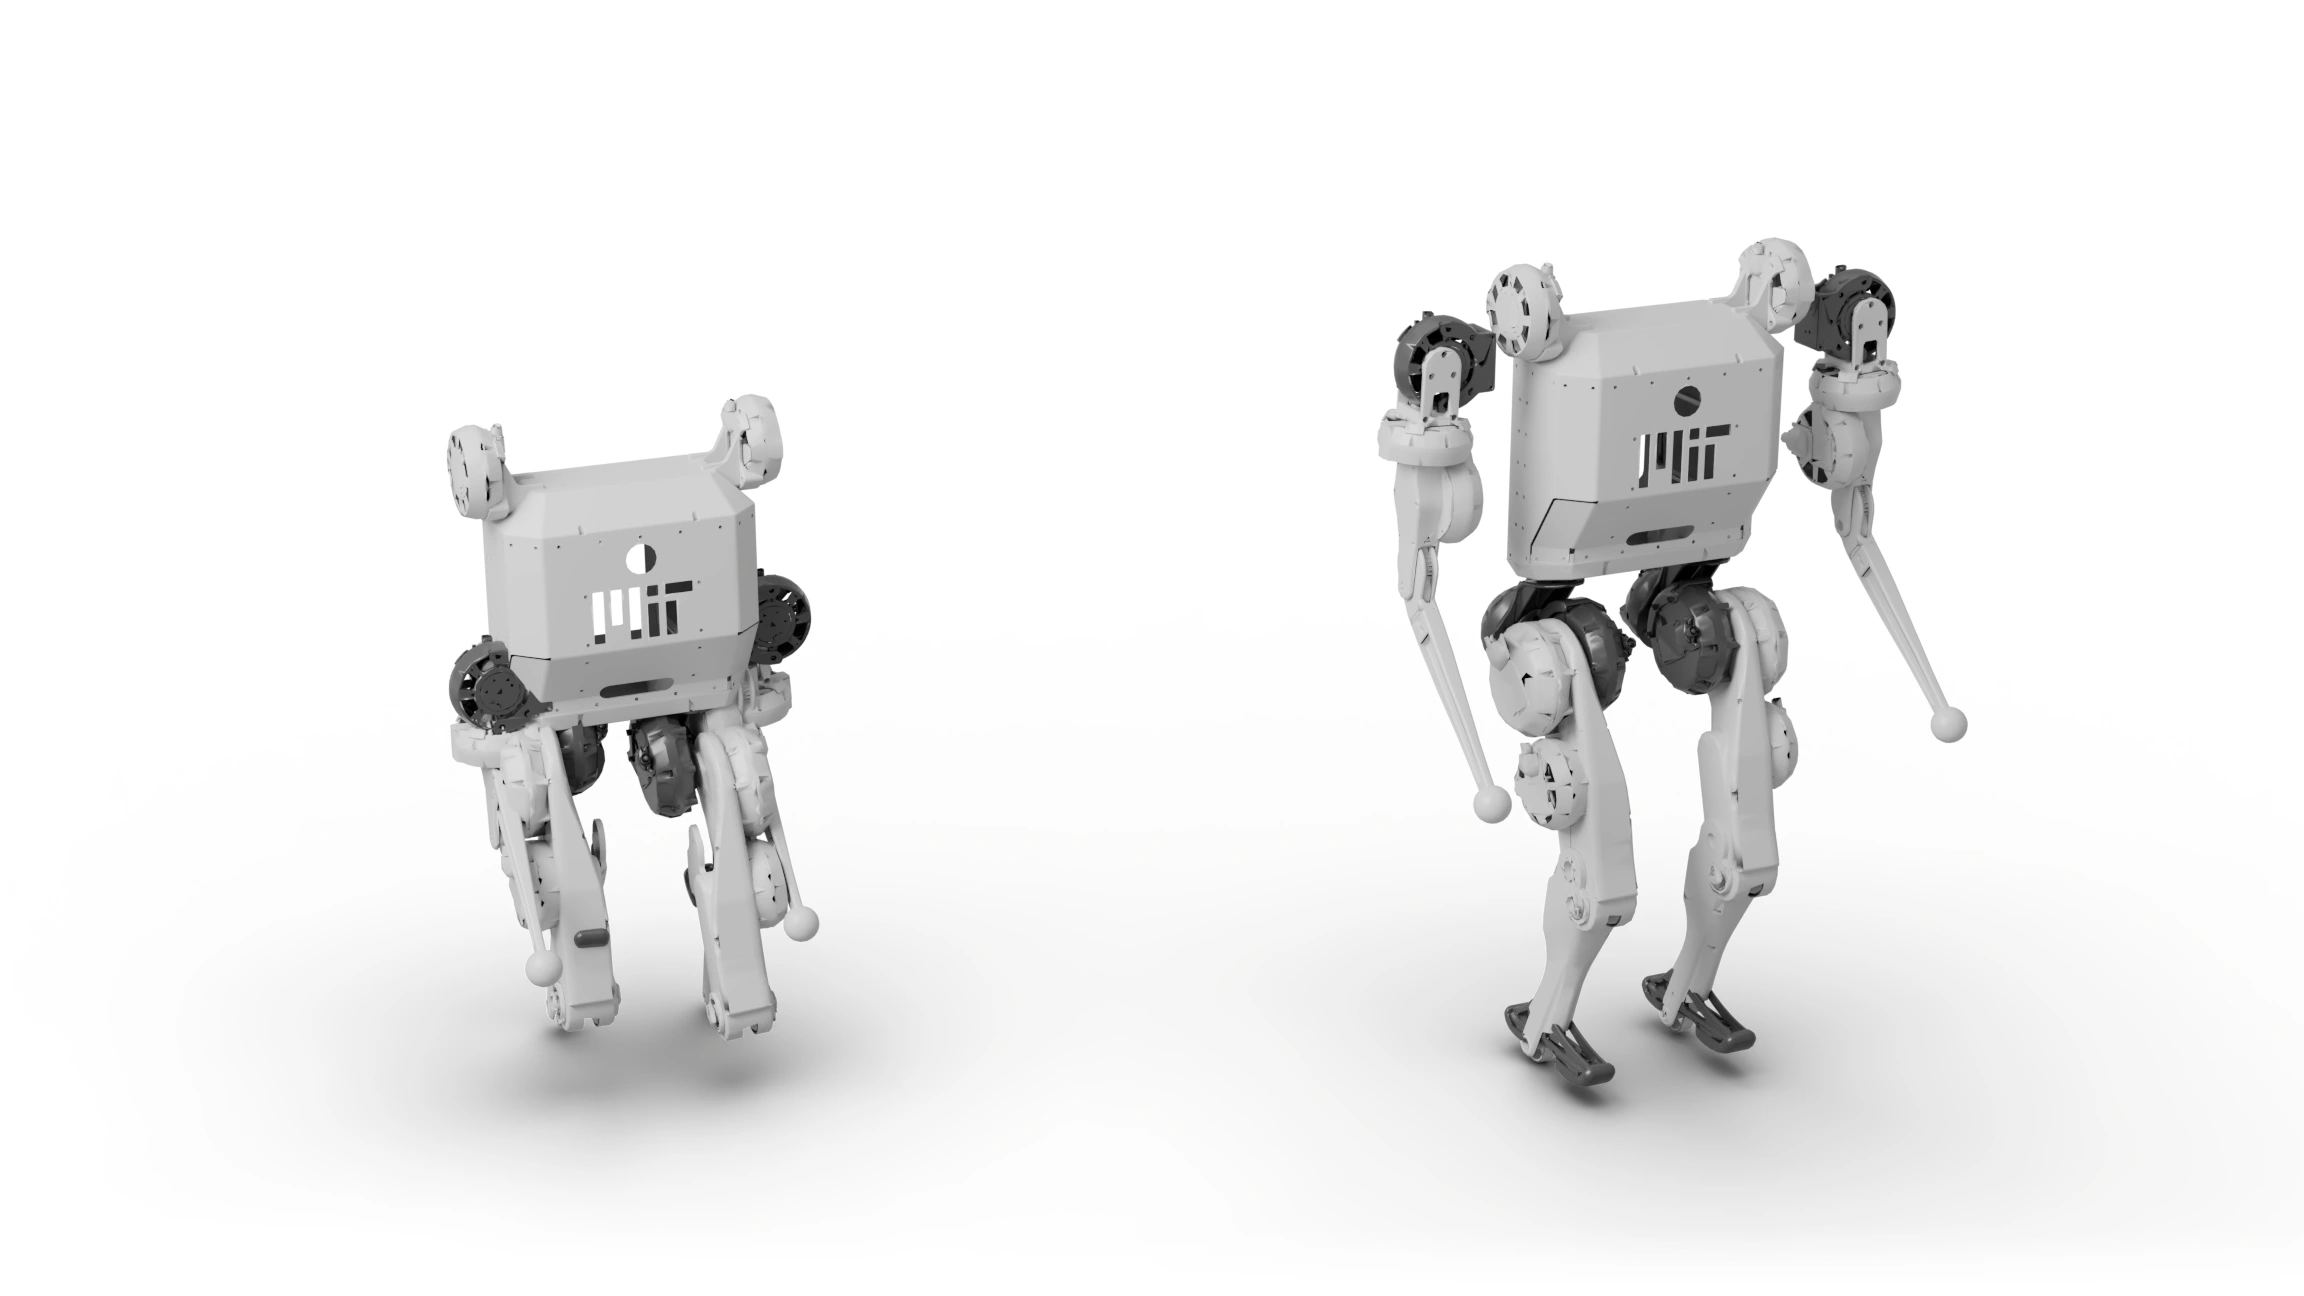
Starting from perturbed designs, VGDS reshapes the embodiment to improve the frozen policy's return. Here we show optimized Unitree Go2, MIT Humanoid, and Fourier GR1-T2 designs. For several tall humanoids, VGDS reshapes robots to be smaller, wider, and more compact, which appears to improve stability.
Design Analysis with Value Gradients
The same value gradients also reveal which design and control parameters matter. We group the update f* − fref by robot component and parameter type, turning the optimized design into a diagnostic tool.
For the MIT Humanoid, the strongest changes are nominal joint positions, PD gains, and reduced foot size. For the Golem, VGDS reduces the action scale, lowers the P gain, and increases the D gain. For the Unitree Go2, the changes are more physical: rear-leg joint axes, foot geometry, and front hip/calf actuator velocity limits. The full improvement comes from coupled high-dimensional updates, but the grouped analysis points to bottlenecks in the design that an engineer should inspect first.
Acknowledgments
This work was funded by the National Science Centre, Poland, under the OPUS Weave grant UMO-2021/43/I/ST6/02711, and by the German Research Foundation (DFG) under grant PE 2315/17-1.
Citation
@article{bohlinger2026shape,
    title={Shape Your Body: Value Gradients for Multi-Embodiment Robot Design},
    author={Bohlinger, Nico and Peters, Jan},
    journal={Conference on Robot Learning},
    year={2026}
}
This website was inspired by Kevin Zakka, Brent Yi, Younghyo Park, and builds on One Policy to Run Them All.